面向模型卡的 Hugging Face 抓取 API
把 Hugging Face URL 发给 Crawl 接口,拿回结构化 Markdown——模型和数据集卡全文、Space 的 metadata 卡、gated 仓库的诚实部分结果。无需账号。
接口 — bashPOST https://api.search1api.com/crawl{ "url": "https://huggingface.co/google-bert/bert-base-uncased" }
专用适配器读公开 Hub API 加仓库 raw README——给的是卡片本体,不是 SPA 壳。
卡片全文转 Markdown——downloads、likes、pipeline 标签、库信息进 metadata。
同样结构的数据集卡——repoType 区分模型、数据集、Space。
gated 模型返回带 gated: true 和明示备注的 metadata——不编造卡片正文。
适用场景
模型调研 / 数据集发现 / 评测管线
输入什么,返回什么
三种 URL 形态:左边是 Hugging Face 向匿名访客实际返回页面的真实截图(经由爬虫同款出口拍摄),右边是 API 返回的 results.content 全文。
huggingface.co/google-bert/bert-base-uncasedHugging Face 实际返回的页面
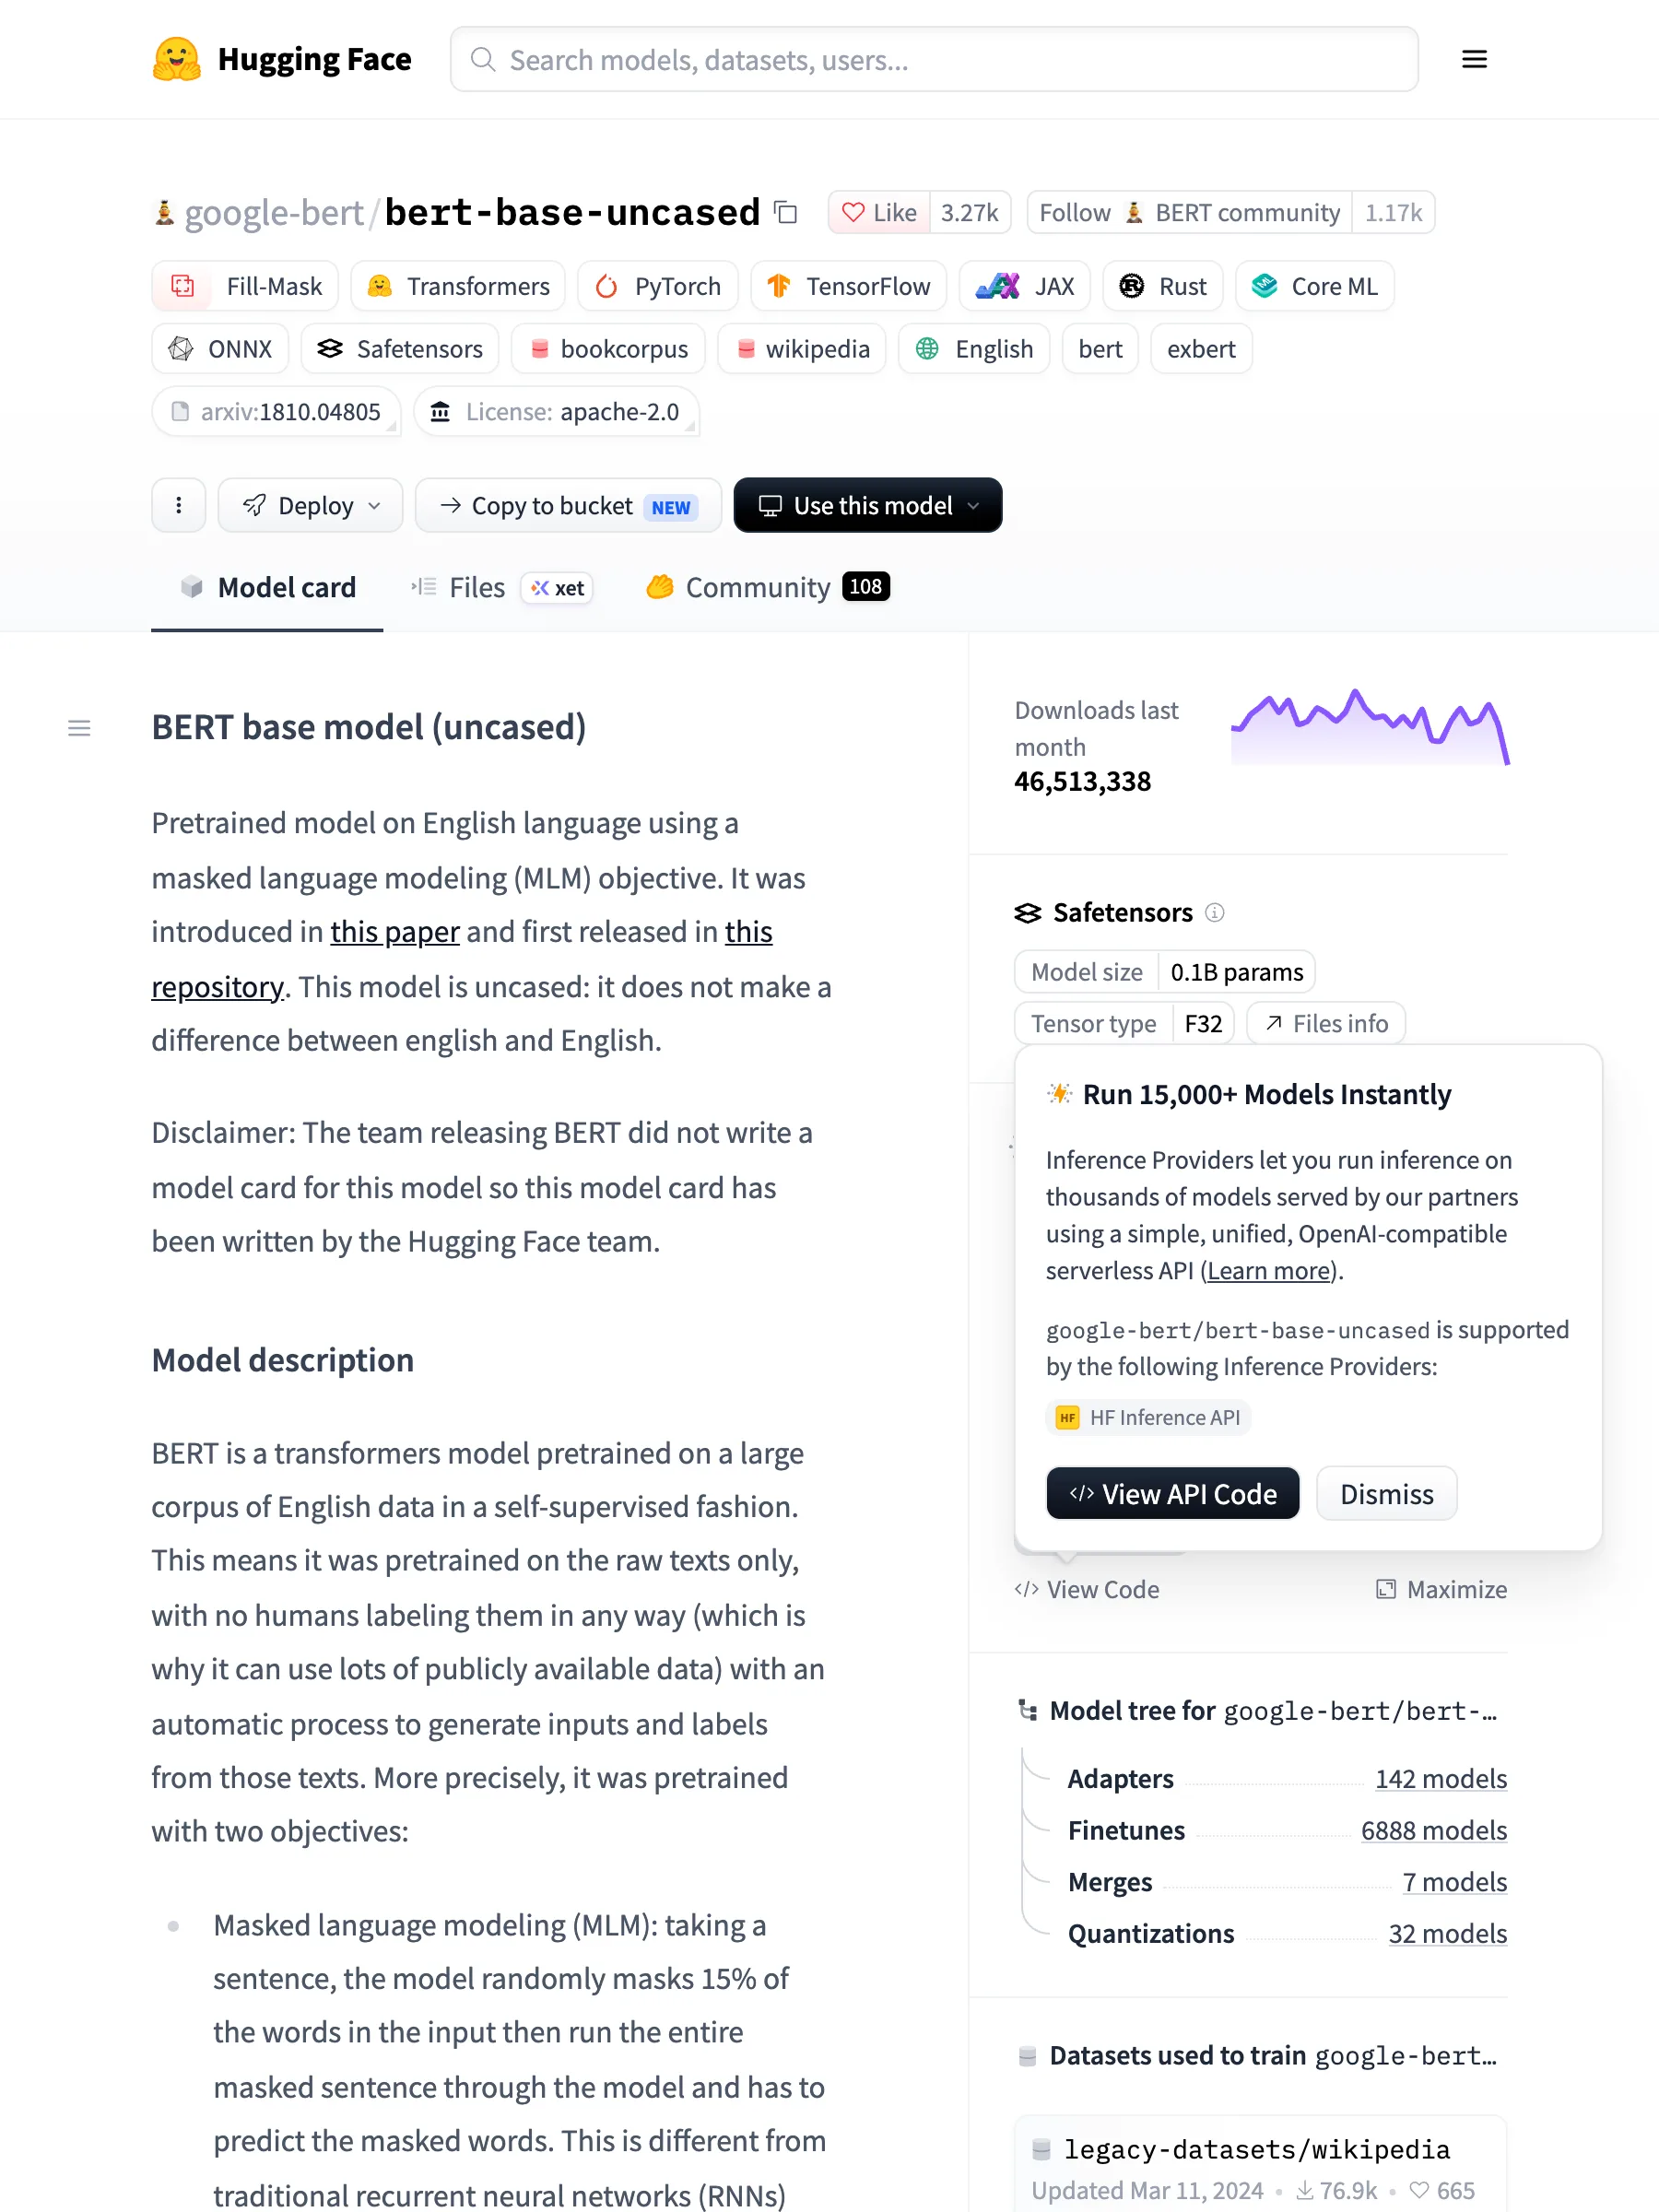
284 KB 渲染 HTML——标签条、部署组件、推理面板
API 返回的数据
markdown# google-bert/bert-base-uncasedType: Model · Task: fill-mask · Library: transformers · License: apache-2.0 · Downloads: 46,513,338 · Likes: 3,266 · Updated: 2024-02-19Tags: transformers, pytorch, tf, jax, rust, coreml, onnx, safetensors, bert, fill-mask, exbert, en, endpoints_compatible# BERT base model (uncased)Pretrained model on English language using a masked language modeling (MLM) objective. It was introduced in[this paper](https://arxiv.org/abs/1810.04805) and first released in[this repository](https://github.com/google-research/bert). This model is uncased: it does not make a differencebetween english and English.Disclaimer: The team releasing BERT did not write a model card for this model so this model card has been written bythe Hugging Face team.## Model descriptionBERT is a transformers model pretrained on a large corpus of English data in a self-supervised fashion. This means itwas pretrained on the raw texts only, with no humans labeling them in any way (which is why it can use lots ofpublicly available data) with an automatic process to generate inputs and labels from those texts. More precisely, itwas pretrained with two objectives:- Masked language modeling (MLM): taking a sentence, the model randomly masks 15% of the words in the input then runthe entire masked sentence through the model and has to predict the masked words. This is different from traditionalrecurrent neural networks (RNNs) that usually see the words one after the other, or from autoregressive models likeGPT which internally masks the future tokens. It allows the model to learn a bidirectional representation of thesentence.- Next sentence prediction (NSP): the models concatenates two masked sentences as inputs during pretraining. Sometimesthey correspond to sentences that were next to each other in the original text, sometimes not. The model then has topredict if the two sentences were following each other or not.This way, the model learns an inner representation of the English language that can then be used to extract featuresuseful for downstream tasks: if you have a dataset of labeled sentences, for instance, you can train a standardclassifier using the features produced by the BERT model as inputs.## Model variationsBERT has originally been released in base and large variations, for cased and uncased input text. The uncased models also strips out an accent markers.Chinese and multilingual uncased and cased versions followed shortly after.Modified preprocessing with whole word masking has replaced subpiece masking in a following work, with the release of two models.Other 24 smaller models are released afterward.The detailed release history can be found on the [google-research/bert readme](https://github.com/google-research/bert/blob/master/README.md) on github.| Model | #params | Language ||------------------------|--------------------------------|-------|| [`bert-base-uncased`](https://huggingface.co/bert-base-uncased) | 110M | English || [`bert-large-uncased`](https://huggingface.co/bert-large-uncased) | 340M | English | sub| [`bert-base-cased`](https://huggingface.co/bert-base-cased) | 110M | English || [`bert-large-cased`](https://huggingface.co/bert-large-cased) | 340M | English || [`bert-base-chinese`](https://huggingface.co/bert-base-chinese) | 110M | Chinese || [`bert-base-multilingual-cased`](https://huggingface.co/bert-base-multilingual-cased) | 110M | Multiple || [`bert-large-uncased-whole-word-masking`](https://huggingface.co/bert-large-uncased-whole-word-masking) | 340M | English || [`bert-large-cased-whole-word-masking`](https://huggingface.co/bert-large-cased-whole-word-masking) | 340M | English |## Intended uses & limitationsYou can use the raw model for either masked language modeling or next sentence prediction, but it's mostly intended tobe fine-tuned on a downstream task. See the [model hub](https://huggingface.co/models?filter=bert) to look forfine-tuned versions of a task that interests you.Note that this model is primarily aimed at being fine-tuned on tasks that use the whole sentence (potentially masked)to make decisions, such as sequence classification, token classification or question answering. For tasks such as textgeneration you should look at model like GPT2.### How to useYou can use this model directly with a pipeline for masked language modeling:```python>>> from transformers import pipeline>>> unmasker = pipeline('fill-mask', model='bert-base-uncased')>>> unmasker("Hello I'm a [MASK] model.")[{'sequence': "[CLS] hello i'm a fashion model. [SEP]",'score': 0.1073106899857521,'token': 4827,'token_str': 'fashion'},{'sequence': "[CLS] hello i'm a role model. [SEP]",'score': 0.08774490654468536,'token': 2535,'token_str': 'role'},{'sequence': "[CLS] hello i'm a new model. [SEP]",'score': 0.05338378623127937,'token': 2047,'token_str': 'new'},{'sequence': "[CLS] hello i'm a super model. [SEP]",'score': 0.04667217284440994,'token': 3565,'token_str': 'super'},{'sequence': "[CLS] hello i'm a fine model. [SEP]",'score': 0.027095865458250046,'token': 2986,'token_str': 'fine'}]```Here is how to use this model to get the features of a given text in PyTorch:```pythonfrom transformers import BertTokenizer, BertModeltokenizer = BertTokenizer.from_pretrained('bert-base-uncased')model = BertModel.from_pretrained("bert-base-uncased")text = "Replace me by any text you'd like."encoded_input = tokenizer(text, return_tensors='pt')output = model(**encoded_input)```and in TensorFlow:```pythonfrom transformers import BertTokenizer, TFBertModeltokenizer = BertTokenizer.from_pretrained('bert-base-uncased')model = TFBertModel.from_pretrained("bert-base-uncased")text = "Replace me by any text you'd like."encoded_input = tokenizer(text, return_tensors='tf')output = model(encoded_input)```### Limitations and biasEven if the training data used for this model could be characterized as fairly neutral, this model can have biasedpredictions:```python>>> from transformers import pipeline>>> unmasker = pipeline('fill-mask', model='bert-base-uncased')>>> unmasker("The man worked as a [MASK].")[{'sequence': '[CLS] the man worked as a carpenter. [SEP]','score': 0.09747550636529922,'token': 10533,'token_str': 'carpenter'},{'sequence': '[CLS] the man worked as a waiter. [SEP]','score': 0.0523831807076931,'token': 15610,'token_str': 'waiter'},{'sequence': '[CLS] the man worked as a barber. [SEP]','score': 0.04962705448269844,'token': 13362,'token_str': 'barber'},{'sequence': '[CLS] the man worked as a mechanic. [SEP]','score': 0.03788609802722931,'token': 15893,'token_str': 'mechanic'},{'sequence': '[CLS] the man worked as a salesman. [SEP]','score': 0.037680890411138535,'token': 18968,'token_str': 'salesman'}]>>> unmasker("The woman worked as a [MASK].")[{'sequence': '[CLS] the woman worked as a nurse. [SEP]','score': 0.21981462836265564,'token': 6821,'token_str': 'nurse'},{'sequence': '[CLS] the woman worked as a waitress. [SEP]','score': 0.1597415804862976,'token': 13877,'token_str': 'waitress'},{'sequence': '[CLS] the woman worked as a maid. [SEP]','score': 0.1154729500412941,'token': 10850,'token_str': 'maid'},{'sequence': '[CLS] the woman worked as a prostitute. [SEP]','score': 0.037968918681144714,'token': 19215,'token_str': 'prostitute'},{'sequence': '[CLS] the woman worked as a cook. [SEP]','score': 0.03042375110089779,'token': 5660,'token_str': 'cook'}]```This bias will also affect all fine-tuned versions of this model.## Training dataThe BERT model was pretrained on [BookCorpus](https://yknzhu.wixsite.com/mbweb), a dataset consisting of 11,038unpublished books and [English Wikipedia](https://en.wikipedia.org/wiki/English_Wikipedia) (excluding lists, tables andheaders).## Training procedure### PreprocessingThe texts are lowercased and tokenized using WordPiece and a vocabulary size of 30,000. The inputs of the model arethen of the form:```[CLS] Sentence A [SEP] Sentence B [SEP]```With probability 0.5, sentence A and sentence B correspond to two consecutive sentences in the original corpus, and inthe other cases, it's another random sentence in the corpus. Note that what is considered a sentence here is aconsecutive span of text usually longer than a single sentence. The only constrain is that the result with the two"sentences" has a combined length of less than 512 tokens.The details of the masking procedure for each sentence are the following:- 15% of the tokens are masked.- In 80% of the cases, the masked tokens are replaced by `[MASK]`.- In 10% of the cases, the masked tokens are replaced by a random token (different) from the one they replace.- In the 10% remaining cases, the masked tokens are left as is.### PretrainingThe model was trained on 4 cloud TPUs in Pod configuration (16 TPU chips total) for one million steps with a batch sizeof 256. The sequence length was limited to 128 tokens for 90% of the steps and 512 for the remaining 10%. The optimizerused is Adam with a learning rate of 1e-4, \\(\beta_{1} = 0.9\\) and \\(\beta_{2} = 0.999\\), a weight decay of 0.01,learning rate warmup for 10,000 steps and linear decay of the learning rate after.## Evaluation resultsWhen fine-tuned on downstream tasks, this model achieves the following results:Glue test results:| Task | MNLI-(m/mm) | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE | Average ||:----:|:-----------:|:----:|:----:|:-----:|:----:|:-----:|:----:|:----:|:-------:|| | 84.6/83.4 | 71.2 | 90.5 | 93.5 | 52.1 | 85.8 | 88.9 | 66.4 | 79.6 |### BibTeX entry and citation info```bibtex@article{DBLP:journals/corr/abs-1810-04805,author = {Jacob Devlin andMing{-}Wei Chang andKenton Lee andKristina Toutanova},title = {{BERT:} Pre-training of Deep Bidirectional Transformers for LanguageUnderstanding},journal = {CoRR},volume = {abs/1810.04805},year = {2018},url = {http://arxiv.org/abs/1810.04805},archivePrefix = {arXiv},eprint = {1810.04805},timestamp = {Tue, 30 Oct 2018 20:39:56 +0100},biburl = {https://dblp.org/rec/journals/corr/abs-1810-04805.bib},bibsource = {dblp computer science bibliography, https://dblp.org}}```<a href="https://huggingface.co/exbert/?model=bert-base-uncased"><img width="300px" src="https://cdn-media.huggingface.co/exbert/button.png"></a>
模型卡全文 — 11 KB · downloads: 46.5M · pipelineTag: "fill-mask"
huggingface.co/datasets/HuggingFaceFW/finewebHugging Face 实际返回的页面
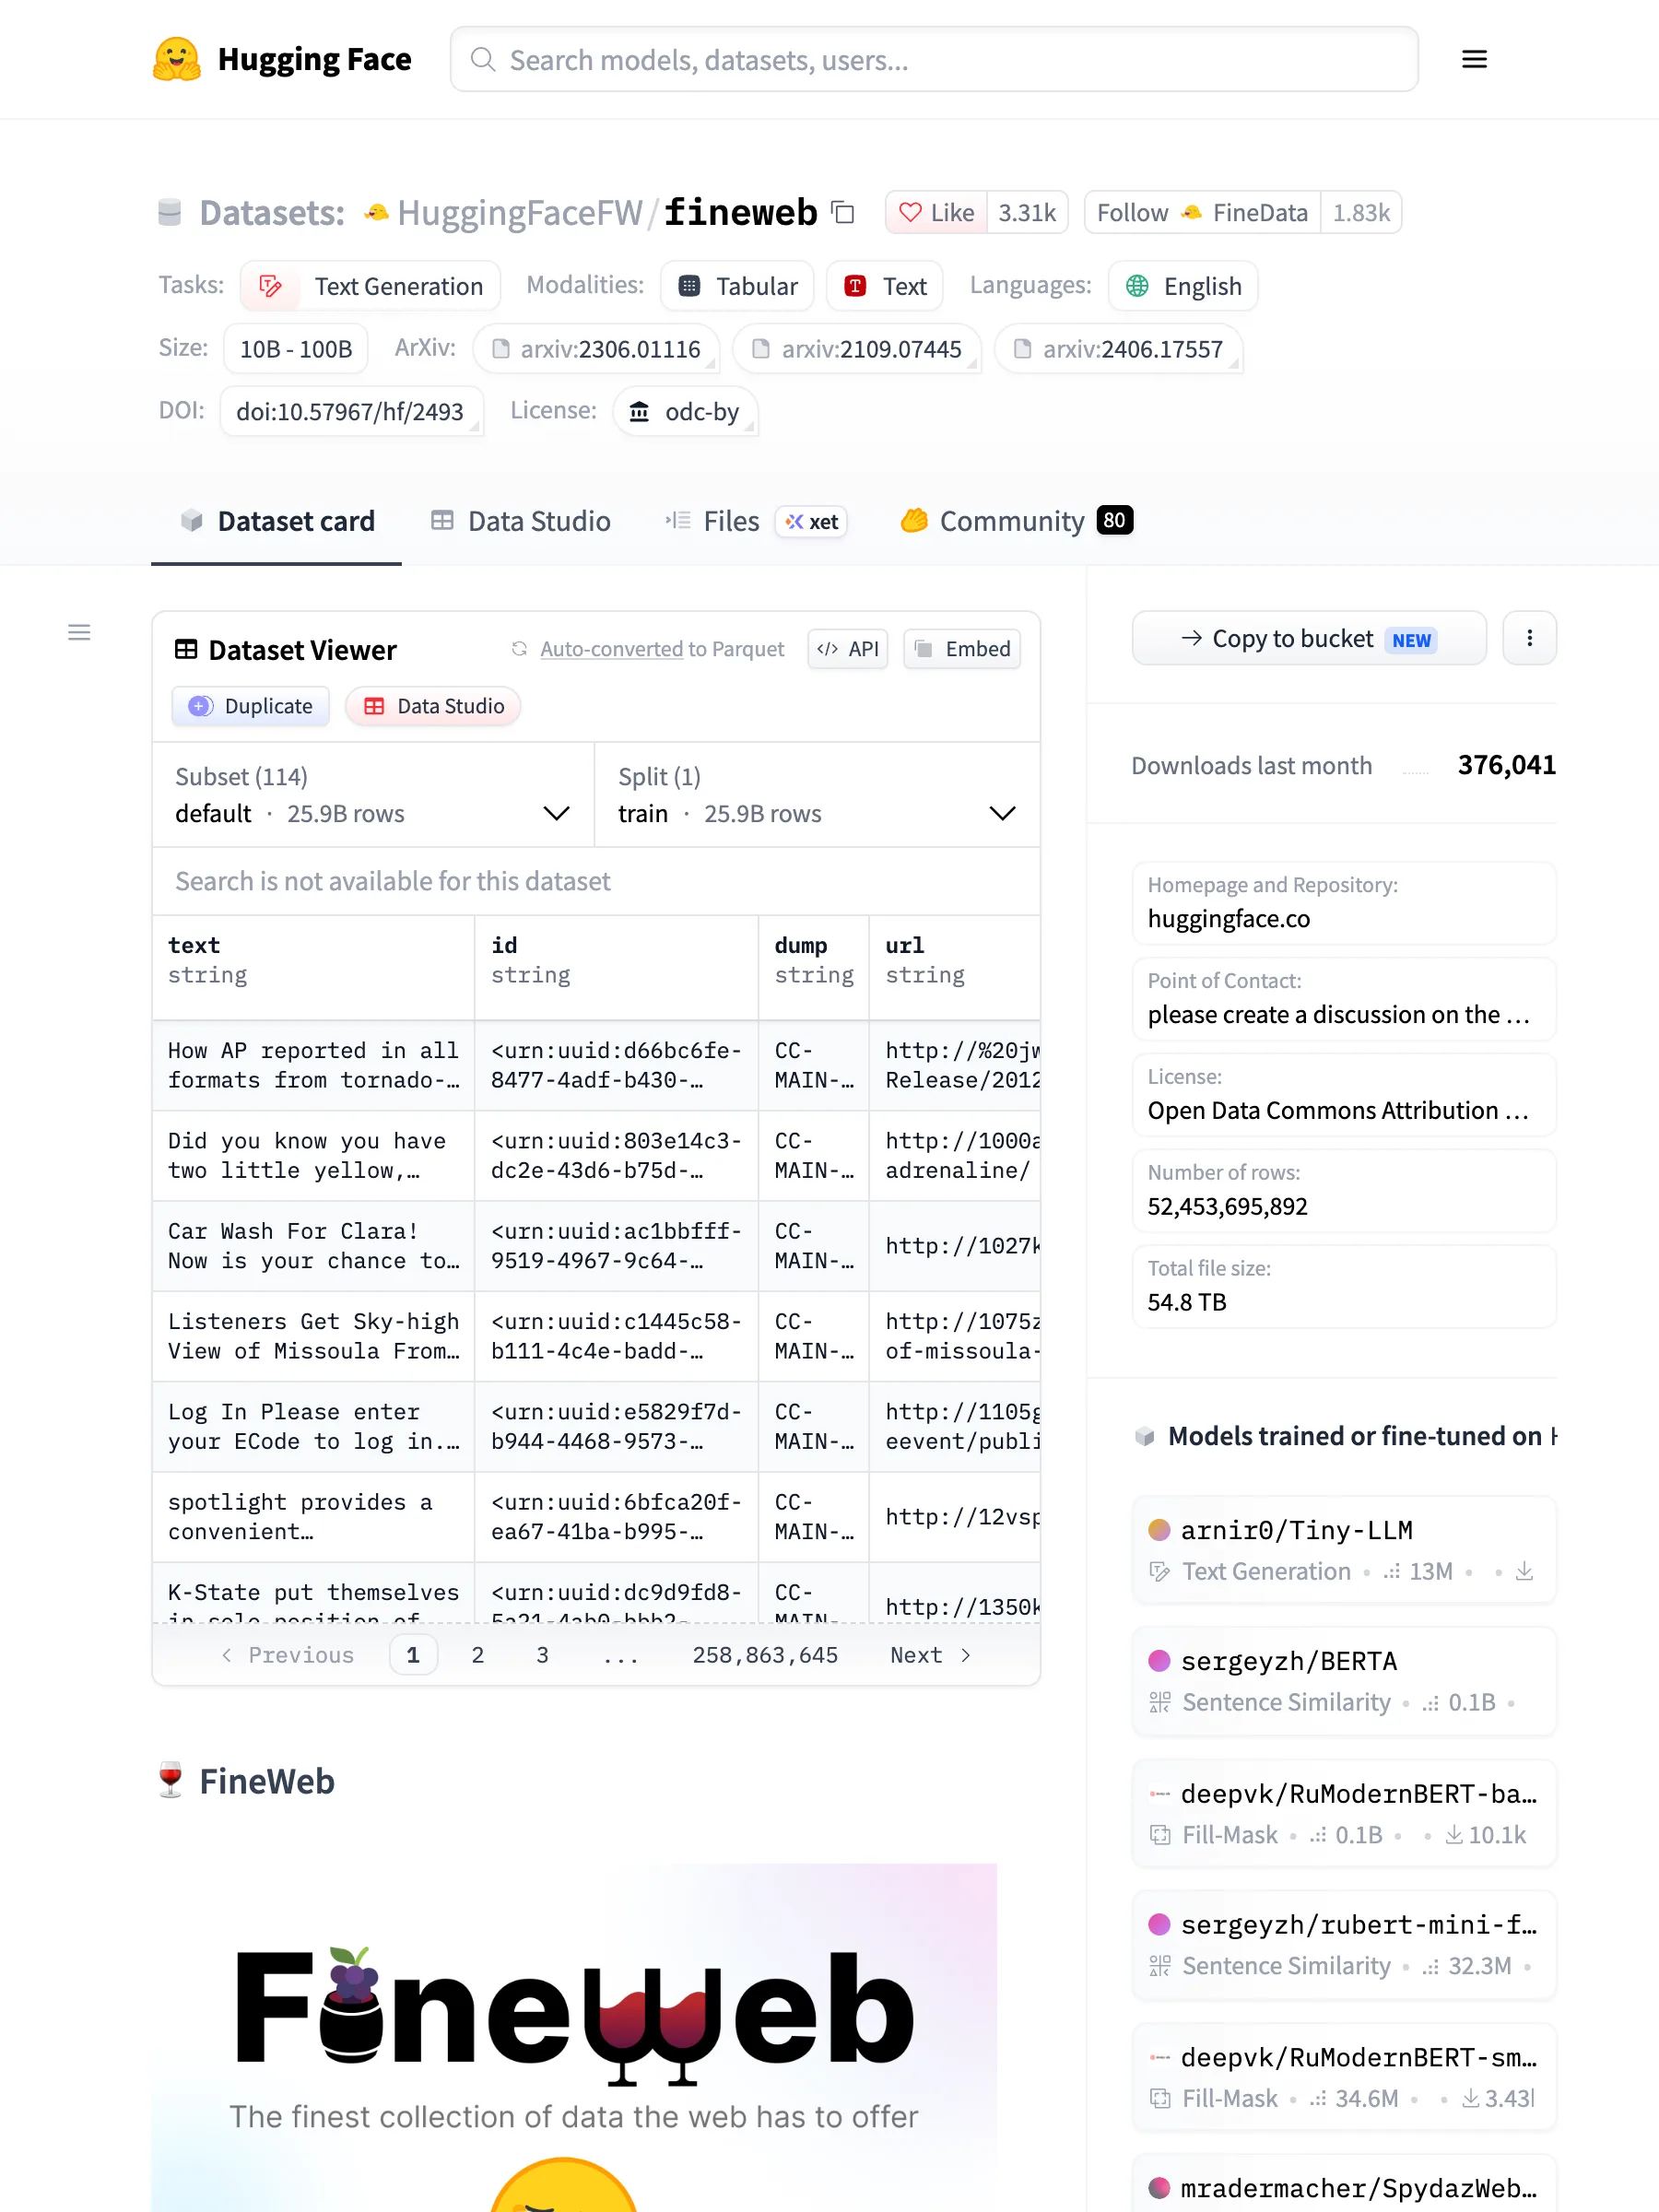
1.3 MB 渲染 HTML——数据集查看器、文件浏览、配置面板
API 返回的数据
markdown# HuggingFaceFW/finewebType: Dataset · License: odc-by · Downloads: 376,041 · Likes: 3,311 · Updated: 2025-07-11# 🍷 FineWeb<center><img src="https://huggingface.co/datasets/HuggingFaceFW/admin/resolve/main/fineweb-logo.png" alt="FineWeb: The finest collection of data the web has to offer"></center>> 15 trillion tokens of the finest data the 🌐 web has to offer# Table of Contents- 🍷 FineWeb* What is it?* What is being released?* Changelog* How to download and use 🍷 FineWeb+ Using 🏭 `datatrove`+ Using `huggingface_hub`+ Using `datasets`* Breakdown by dump/crawl* Dataset performance evaluation and ablations+ Hyper-parameters for ablation models+ Ablation evaluation benchmarks+ Comparison with other datasets- Dataset card for 🍷 FineWeb* Dataset Summary* Dataset Structure+ Data Instances+ Data Fields+ Data Splits* Dataset Creation+ Curation Rationale+ Source Data+ Data processing steps+ Annotations+ Personal and Sensitive Information* Considerations for Using the Data+ Social Impact of Dataset+ Discussion of Biases+ Other Known Limitations* Additional Information+ Licensing Information+ Future work+ Citation Information## What is it?The 🍷 FineWeb dataset consists of more than **18.5T tokens** (originally 15T tokens) of cleaned and deduplicated english web data from CommonCrawl. The data processing pipeline is optimized for LLM performance and ran on the 🏭 [`datatrove`](https://github.com/huggingface/datatrove/) library, our large scale data processing library.🍷 FineWeb was originally meant to be a fully open replication of 🦅 [RefinedWeb](https://huggingface.co/papers/2306.01116), with a release of the **full dataset** under the **ODC-By 1.0 license**. However, by carefully adding additional filtering steps, we managed to push the performance of 🍷 FineWeb well above that of the original 🦅 RefinedWeb, and models trained on our dataset also outperform models trained on other commonly used high quality web datasets (like C4, Dolma-v1.6, The Pile, SlimPajama, RedPajam2) on our aggregate group of [benchmark tasks](https://huggingface.co/datasets/HuggingFaceFW/fineweb/blob/main/lighteval_tasks.py).That said, we think there is still room for additional filtering and improvement and intend to continue exploring how to improve the dataset quality in coming versions of 🍷 FineWeb.## What is being released?Along with the dataset, which includes all CommonCrawl dumps since 2013, we also share all the code needed to fully reproduce our processing setup using the 🏭 [`datatrove`](https://github.com/huggingface/datatrove/) library [here](https://github.com/huggingface/datatrove/blob/main/examples/fineweb.py). To enable full replication of our results, we have also published the small ablation models we have trained using [`nanotron`](https://github.com/huggingface/nanotron/) to validate the dataset and compare it with other reference datasets. You will find them [here](https://huggingface.co/collections/HuggingFaceFW/ablation-models-662457b0d213e8c14fe47f32), with checkpoints every 1000 steps. We have also published our evaluation results [here](https://huggingface.co/datasets/HuggingFaceFW/fineweb/blob/main/eval_results.csv). Our evaluation setup is available [here](https://huggingface.co/datasets/HuggingFaceFW/fineweb/blob/main/lighteval_tasks.py).You will find details on the different processing decisions we took and some interesting explorations of deduplication methods on our [blogpost](https://huggingface.co/spaces/HuggingFaceFW/blogpost-fineweb-v1).## Changelog_Previous versions remain available in the branch `version name`._- **v1.4.0 (11-07-2025):** Added 6 new snapshots: `CC-MAIN-2025-05`, `CC-MAIN-2025-08`, `CC-MAIN-2025-13`, `CC-MAIN-2025-18`, `CC-MAIN-2025-21`, and `CC-MAIN-2025-26` (January to June 2025)- **v1.3.0 (31-01-2025):** Fixed an issue with some dumps where some documents hadn't been processed: `CC-MAIN-2024-10`, `CC-MAIN-2024-18`, `CC-MAIN-2024-22`, `CC-MAIN-2024-26`, `CC-MAIN-2024-30`, `CC-MAIN-2024-33`, `CC-MAIN-2024-38`, `CC-MAIN-2024-42`, `CC-MAIN-2024-46` -- they now contain more data (~400B additional tokens). We also removed specific domains in response to a [C&D notice](https://huggingface.co/datasets/huggingface-legal/takedown-notices/blob/main/2025/2025-01-22-Torstar.md).- **v1.2.0 (03-01-2025):** Added 8 new snapshots: `CC-MAIN-2024-22`, `CC-MAIN-2024-26`, `CC-MAIN-2024-30`, `CC-MAIN-2024-33`, `CC-MAIN-2024-38`, `CC-MAIN-2024-42`, `CC-MAIN-2024-46`, `CC-MAIN-2024-51`, covering May to December 2024.- **v1.1.0 (31-05-2024):** We reprocessed and reuploaded 11 dumps, `CC-MAIN-2021-49` to `CC-MAIN-2023-40`, as we found a bug on their deduplication. We also added the most recent dump: `CC-MAIN-2024-18`, crawled over April 2024. Expect a small perf improvement- **v1.0.0 (21-04-2024):** Initial version## How to download and use 🍷 FineWebYou can load the full dataset or a specific crawl/dump (see table below). Dumps have the format `CC-MAIN-(year)-(week number)`.### (Smaller) sample versionsAlong with config `default` (all the data), and the configs for each individual dump, you can also download the following configs:- `sample-350BT`: a subset randomly sampled from the whole dataset of around 350B gpt2 tokens (388GB)- `sample-100BT`: a subset randomly sampled from the whole dataset of around 100B gpt2 tokens (277.4GB)- `sample-10BT`: a subset randomly sampled from the whole dataset of around 10B gpt2 tokens (27.6GB)`sample-10B` was sampled from `sample-100B` which in turn was sampled from `sample-350BT`.### Using 🏭 [`datatrove`](https://github.com/huggingface/datatrove/)```pythonfrom datatrove.pipeline.readers import ParquetReader# limit determines how many documents will be streamed (remove for all)# to fetch a specific dump: hf://datasets/HuggingFaceFW/fineweb/data/CC-MAIN-2024-10# replace "data" with "sample/100BT" to use the 100BT sampledata_reader = ParquetReader("hf://datasets/HuggingFaceFW/fineweb/data", limit=1000)for document in data_reader():# do something with documentprint(document)################################ OR for a processing pipeline:###############################from datatrove.executor import LocalPipelineExecutorfrom datatrove.pipeline.readers import ParquetReaderfrom datatrove.pipeline.filters import LambdaFilterfrom datatrove.pipeline.writers import JsonlWriterpipeline_exec = LocalPipelineExecutor(pipeline=[# replace "data/CC-MAIN-2024-10" with "sample/100BT" to use the 100BT sampleParquetReader("hf://datasets/HuggingFaceFW/fineweb/data/CC-MAIN-2024-10", limit=1000),LambdaFilter(lambda doc: "hugging" in doc.text),JsonlWriter("some-output-path")],tasks=10)pipeline_exec.run()```### Using `huggingface_hub````pythonfrom huggingface_hub import snapshot_downloadfolder = snapshot_download("HuggingFaceFW/fineweb",repo_type="dataset",local_dir="./fineweb/",# replace "data/CC-MAIN-2023-50/*" with "sample/100BT/*" to use the 100BT sampleallow_patterns="data/CC-MAIN-2023-50/*")```For faster downloads, make sure to install `pip install huggingface_hub[hf_transfer]` and set the environment variable `HF_HUB_ENABLE_HF_TRANSFER=1`.### Using `datasets````pythonfrom datasets import load_dataset# use name="sample-10BT" to use the 10BT samplefw = load_dataset("HuggingFaceFW/fineweb", name="CC-MAIN-2024-10", split="train", streaming=True)```## Breakdown by dump/crawl| Dump | Time period | Disk size (GB) | gpt2 tokens (billions) || --- | --- |----------------|------------------------|| CC-MAIN-2025-26 | June 2025 | 419.6 | 152.4 || CC-MAIN-2025-21 | May 2025 | 462.8 | 168.1 || CC-MAIN-2025-18 | April 2025 | 506.8 | 184.2 || CC-MAIN-2025-13 | March 2025 | 491.1 | 178.5 || CC-MAIN-2025-08 | February 2025 | 472.0 | 171.6 || CC-MAIN-2025-05 | January 2025 | 558.8 | 203.5 || CC-MAIN-2024-51 | December 2024 | 362.6 | 131.2 || CC-MAIN-2024-46 | November 2024 | 474.6 | 172.9 || CC-MAIN-2024-42 | October 2024 | 434.0 | 158.1 || CC-MAIN-2024-38 | September 2024 | 506.2 | 184.6 || CC-MAIN-2024-33 | August 2024 | 400.6 | 145.9 || CC-MAIN-2024-30 | July 2024 | 451.3 | 164.6 || CC-MAIN-2024-26 | June 2024 | 496.5 | 181.2 || CC-MAIN-2024-22 | May 2024 | 499.7 | 182.5 || CC-MAIN-2024-18 | April 2024 | 520.6 | 190.3 || CC-MAIN-2024-10 | February/March 2024 | 581.3 | 212.6 || CC-MAIN-2023-50 | November/December 2023 | 650.0 | 239.7 || CC-MAIN-2023-40 | September/October 2023 | 668.7 | 252.0 || CC-MAIN-2023-23 | May/June 2023 | 654.4 | 249.2 || CC-MAIN-2023-14 | March/April 2023 | 621.3 | 236.5 || CC-MAIN-2023-06 | January/February 2023 | 621.9 | 233.9 || CC-MAIN-2022-49 | November/December 2022 | 631.2 | 237.5 || CC-MAIN-2022-40 | September/October 2022 | 606.4 | 228.7 || CC-MAIN-2022-33 | August 2022 | 434.6 | 163.5 || CC-MAIN-2022-27 | June/July 2022 | 574.9 | 216.1 || CC-MAIN-2022-21 | May 2022 | 646.4 | 242.7 || CC-MAIN-2022-05 | January 2022 | 520.1 | 195.4 || CC-MAIN-2021-49 | November/December 2021 | 413.7 | 155.5 || CC-MAIN-2021-43 | October 2021 | 601.5 | 221.0 || CC-MAIN-2021-43 | October 2021 | 601.5 | 221.0 || CC-MAIN-2021-39 | September 2021 | 518.9 | 190.6 || CC-MAIN-2021-31 | July/August 2021 | 593.9 | 217.7 || CC-MAIN-2021-25 | June 2021 | 424.4 | 155.7 || CC-MAIN-2021-21 | May 2021 | 455.9 | 167.4 || CC-MAIN-2021-17 | April 2021 | 556.0 | 204.1 || CC-MAIN-2021-10 | February/March 2021 | 463.2 | 169.6 || CC-MAIN-2021-04 | January 2021 | 562.4 | 205.4 || CC-MAIN-2020-50 | November/December 2020 | 422.8 | 154.3 || CC-MAIN-2020-45 | October 2020 | 426.9 | 155.8 || CC-MAIN-2020-40 | September 2020 | 555.5 | 202.4 || CC-MAIN-2020-34 | August 2020 | 379.6 | 138.7 || CC-MAIN-2020-29 | July 2020 | 489.6 | 178.7 || CC-MAIN-2020-24 | May/June 2020 | 398.7 | 145.1 || CC-MAIN-2020-16 | March/April 2020 | 454.0 | 165.6 || CC-MAIN-2020-10 | February 2020 | 369.6 | 134.7 || CC-MAIN-2020-05 | January 2020 | 483.3 | 176.4 || CC-MAIN-2019-51 | December 2019 | 359.3 | 130.9 || CC-MAIN-2019-47 | November 2019 | 395.4 | 144.0 || CC-MAIN-2019-43 | October 2019 | 422.3 | 153.9 || CC-MAIN-2019-39 | September 2019 | 394.4 | 143.7 || CC-MAIN-2019-35 | August 2019 | 454.2 | 165.4 || CC-MAIN-2019-30 | July 2019 | 416.6 | 151.5 || CC-MAIN-2019-26 | June 2019 | 412.9 | 150.1 || CC-MAIN-2019-22 | May 2019 | 432.8 | 157.4 || CC-MAIN-2019-18 | April 2019 | 426.7 | 155.3 || CC-MAIN-2019-13 | March 2019 | 417.8 | 152.1 || CC-MAIN-2019-09 | February 2019 | 467.2 | 169.9 || CC-MAIN-2019-04 | January 2019 | 438.1 | 158.7 || CC-MAIN-2018-51 | December 2018 | 498.6 | 180.8 || CC-MAIN-2018-47 | November 2018 | 437.7 | 158.9 || CC-MAIN-2018-43 | October 2018 | 468.8 | 169.9 || CC-MAIN-2018-39 | September 2018 | 429.2 | 155.2 || CC-MAIN-2018-34 | August 2018 | 408.2 | 148.0 || CC-MAIN-2018-30 | July 2018 | 501.5 | 181.4 || CC-MAIN-2018-26 | June 2018 | 467.5 | 170.0 || CC-MAIN-2018-22 | May 2018 | 398.6 | 144.2 || CC-MAIN-2018-17 | April 2018 | 435.1 | 158.1 || CC-MAIN-2018-13 | March 2018 | 471.5 | 171.5 || CC-MAIN-2018-09 | February 2018 | 490.2 | 178.0 || CC-MAIN-2018-05 | January 2018 | 493.5 | 180.7 || CC-MAIN-2017-51 | December 2017 | 442.6 | 161.5 || CC-MAIN-2017-47 | November 2017 | 457.9 | 167.1 || CC-MAIN-2017-43 | October 2017 | 535.6 | 194.9 || CC-MAIN-2017-39 | September 2017 | 444.5 | 162.3 || CC-MAIN-2017-34 | August 2017 | 503.2 | 183.4 || CC-MAIN-2017-30 | July 2017 | 439.2 | 161.2 || CC-MAIN-2017-26 | June 2017 | 491.5 | 179.8 || CC-MAIN-2017-22 | May 2017 | 441.0 | 161.5 || CC-MAIN-2017-17 | April 2017 | 596.8 | 218.6 || CC-MAIN-2017-13 | March 2017 | 579.8 | 212.1 || CC-MAIN-2017-09 | February 2017 | 492.2 | 180.2 || CC-MAIN-2017-04 | January 2017 | 474.3 | 174.4 || CC-MAIN-2016-50 | December 2016 | 448.9 | 165.4 || CC-MAIN-2016-44 | October 2016 | 467.8 | 172.0 || CC-MAIN-2016-40 | September 2016 | 386.1 | 142.8 || CC-MAIN-2016-36 | August 2016 | 339.6 | 126.3 || CC-MAIN-2016-30 | July 2016 | 346.0 | 128.4 || CC-MAIN-2016-26 | June 2016 | 256.5 | 95.5 || CC-MAIN-2016-22 | May 2016 | 310.9 | 115.4 || CC-MAIN-2016-18 | April 2016 | 298.1 | 110.8 || CC-MAIN-2016-07 | February 2016 | 342.7 | 127.2 || CC-MAIN-2015-48 | November 2015 | 353.9 | 131.3 || CC-MAIN-2015-40 | September 2015 | 284.0 | 105.5 || CC-MAIN-2015-35 | August 2015 | 359.4 | 133.2 || CC-MAIN-2015-32 | July 2015 | 352.4 | 130.1 || CC-MAIN-2015-27 | June 2015 | 335.5 | 124.0 || CC-MAIN-2015-22 | May 2015 | 380.2 | 140.4 || CC-MAIN-2015-18 | April 2015 | 389.0 | 143.8 || CC-MAIN-2015-14 | March 2015 | 337.5 | 124.5 || CC-MAIN-2015-11 | February 2015 | 361.4 | 133.3 || CC-MAIN-2015-06 | January 2015 | 356.1 | 131.3 || CC-MAIN-2014-52 | December 2014 | 388.5 | 143.3 || CC-MAIN-2014-49 | November 2014 | 319.9 | 117.7 || CC-MAIN-2014-42 | October 2014 | 371.1 | 136.4 || CC-MAIN-2014-41 | September 2014 | 408.1 | 150.2 || CC-MAIN-2014-35 | August 2014 | 395.7 | 145.6 || CC-MAIN-2014-23 | July 2014 | 425.0 | 156.5 || CC-MAIN-2014-15 | April 2014 | 369.1 | 135.7 || CC-MAIN-2014-10 | March 2014 | 396.2 | 146.2 || CC-MAIN-2013-48 | Winter 2013 | 396.8 | 145.9 || CC-MAIN-2013-20 | Summer 2013 | 393.9 | 144.5 || Total | | 50,446.9 | 18,527.0 |## Dataset performance evaluation and ablationsWe conducted our dataset performance ablations and evaluations by training a series of 1.8B parameters models on 27 billion tokens. To compare 🍷 FineWeb with other datasets, we also trained one of these 1.8B models per target dataset, on 350 billion tokens sampled from it (or the entire dataset when its size was < 350 billion tokens).### Hyper-parameters for ablation modelsThe detailed configurations for training the 1.8B parameters ablation model can be found here (link will be added soon).### Ablation evaluation benchmarksTo conduct the ablations for each of our dataset filtering choices, we selected a set of benchmarks which we identified as “high-signal” benchmarks. These benchmarks were selected according to the following criteria:- small variance between runs trained on different samplings of the same dataset- performance increasing monotically during training (or close)- separation between runs on datasets of known quality (C4, The Pile, RedPajama) higher than the variance between runs with various modeling/data seedsWe used the following list of benchmark for our ablation runs:- commonsense_qa (acc/acc_norm)- hellaswag (acc/acc_norm)- openbookqa (acc/acc_norm)- piqa (acc/acc_norm)- siqa (acc/acc_norm)- winogrande (acc/acc_norm)- arc (acc/acc_norm)- mmlu (acc/acc_norm)To compare runs we consider an aggregate score, the average of the scores for these tasks.The prompts for all these benchmarks are formatted in order to compute and compare the log-likelihood of the full answers for each multiple choice question. All the implementation details for the benchmarks are available in `lighteval` [here](https://huggingface.co/datasets/HuggingFaceFW/fineweb/blob/main/lighteval_tasks.py).### Comparison with other datasetsWe compared 🍷 FineWeb with the following datasets:- [RefinedWeb](https://huggingface.co/datasets/tiiuae/falcon-refinedweb)- [C4](https://huggingface.co/datasets/allenai/c4)- [Dolma v1.6](https://huggingface.co/datasets/allenai/dolma) (the CommonCrawl part)- [The Pile](https://huggingface.co/datasets/EleutherAI/pile)- [SlimPajama](https://huggingface.co/datasets/cerebras/SlimPajama-627B)- [RedPajama2](https://huggingface.co/datasets/togethercomputer/RedPajama-Data-V2) (deduplicated)You will find these models on [this collection](https://huggingface.co/collections/HuggingFaceFW/ablation-models-662457b0d213e8c14fe47f32). We have uploaded checkpoints at every 1000 training steps. You will also find our full [evaluation results here](https://huggingface.co/datasets/HuggingFaceFW/fineweb/blob/main/eval_results.csv).<center><img src="https://huggingface.co/datasets/HuggingFaceFW/admin/resolve/main/fineweb-ablations.png" alt="ablations"></center>_Note:_ The plot is smoothed by averaging 5k steps in a rolling window.# Dataset card for 🍷 FineWeb## Dataset Description- **Homepage and Repository:** [https://huggingface.co/datasets/HuggingFaceFW/fineweb](https://huggingface.co/datasets/HuggingFaceFW/fineweb)- **Point of Contact:** please create a discussion on the Community tab- **License:** Open Data Commons Attribution License (ODC-By) v1.0### Dataset SummaryThis dataset was created by processing 96 [CommonCrawl](https://commoncrawl.org/) dumps comprising web data crawled from the summer of 2013 to April of 2024. 🍷 FineWeb includes a variety of domains and topics in English and is primarily intended to be used as a research artifact on public data in the context of pretraining dataset for large language models. The CommonCrawl data was carefully processed, filtered and deduplicated with the 🏭 [`datatrove`](https://github.com/huggingface/datatrove/) library, resulting in the largest publicly available clean LLM pretraining dataset, counting around 15 trillion tokens (gpt2 tokenizer).## Dataset Structure### Data InstancesThe following is an example sample from the dataset. It is part of the `CC-MAIN-2021-43` and was crawled on `2021-10-15T21:20:12Z`.```json{"text": "This is basically a peanut flavoured cream thickened with egg yolks and then set into a ramekin on top of some jam. Tony, one of the Wedgwood chefs, suggested sprinkling on some toasted crushed peanuts at the end to create extra crunch, which I thought was a great idea. The result is excellent.","id": "<urn:uuid:e5a3e79a-13d4-4147-a26e-167536fcac5d>","dump": "CC-MAIN-2021-43","url": "<http://allrecipes.co.uk/recipe/24758/peanut-butter-and-jam-creme-brulee.aspx?o_is=SimilarRecipes&o_ln=SimRecipes_Photo_7>","date": "2021-10-15T21:20:12Z","file_path": "s3://commoncrawl/crawl-data/CC-MAIN-2021-43/segments/1634323583083.92/warc/CC-MAIN-20211015192439-20211015222439-00600.warc.gz","language": "en","language_score": 0.948729,"token_count": 69}```### Data Fields- `text` (string): the main text content- `id` (string): original unique identifier for this sample from CommonCrawl- `dump` (string): the CommonCrawl dump this sample was a part of- `url` (string): url to the original page where `text` was present- `date` (string): crawl date (from CommonCrawl)- `file_path` (string): s3 path for the individual CommonCrawl warc file containing this sample- `language` (string): `en` for all the samples in this dataset- `language_score` (float): language prediction score (`0.01.0`) as reported by the [fastText language classifier](https://github.com/huggingface/datatrove/blob/main/src/datatrove/pipeline/filters/language_filter.py)- `token_count` (int): number of tokens when applying the `gpt2` tokenizer to this sample### Data SplitsThe `default` subset includes the entire dataset. If you would like to only use the data from a particular [CommonCrawl dump](https://commoncrawl.org/overview), you can use the dump name as a subset. You will find the full list of available dumps on the table above.From experiments we have run, not all dumps give the same performance. For relatively small trainings (<550 billion tokens) we recommend using the recent `CC-MAIN-2023-50`, `CC-MAIN-2024-10` and `CC-MAIN-2024-18`.## Dataset Creation### Curation RationaleWhile multiple open-weights models have regularly been released in recent months, these releases often do not include the model's training data. With 🍷 FineWeb we aim to provide the open source community with a very large clean pretraining dataset that can be used to push the envelope on truly open source models (open source models where data is also released).### Source DataThe source data consists of webpages crawled by the CommonCrawl foundation over the 2013-2024 time period.We then extracted the main page text from the html of each webpage, carefully filtered each sample and deduplicated each individual CommonCrawl dump/crawl.While we originally intended to deduplicate the dataset as a whole, our ablations showed that training on a sampling of individually deduplicated dumps/crawls outperformed training on a sampling of all the dumps/crawls deduplicated together. You will find more details on our [blogpost](https://huggingface.co/spaces/HuggingFaceFW/blogpost-fineweb-v1).### Data processing stepsWe used the 🏭 `datatrove` library to process the data.You can find a **working script** that launches the [entire processing pipeline here](https://github.com/huggingface/datatrove/blob/main/examples/fineweb.py).The data processing pipeline consists of:1. [Url Filtering](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/filters/url_filter.py), removing documents originating from Malicious and NSFW websites, using both block-list as well as subwords detection2. [Trafilatura](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/extractors/trafilatura.py) text extraction on the raw HTML from CommonCrawl’s warc files3. [FastText LanguageFilter](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/filters/language_filter.py), removing any document with `en` language score lower than **0.65**4. Quality filtering1. [Gopher Repetition /](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/filters/gopher_repetition_filter.py) [Quality](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/filters/gopher_quality_filter.py)2. [C4 Quality filters](https://github.com/huggingface/datatrove/blob/9a88bebc86a554f8521faa70b12ad4fa0c227537/src/datatrove/pipeline/filters/c4_quality_filter.py) except `terminal_punct` rule3. [FineWeb custom filters](https://github.com/huggingface/datatrove/blob/05194d3960741e7d5c0bd0d6dd69d44514622549/src/datatrove/pipeline/filters/fineweb_quality_filter.py), consisting of heuristics for removing list-like documents, documents with repeated lines and documents with likely wrong line formatting.5. [MinHash deduplication](https://github.com/huggingface/datatrove/blob/6daa5e879e06b21e6886b37e2b1be4ae58a658b6/src/datatrove/pipeline/dedup/minhash.py) with each crawl deduplicated individually (5-grams, 14x8 hash functions)6. [PII Formatting](https://github.com/huggingface/datatrove/blob/main/src/datatrove/pipeline/formatters/pii.py) to anonymize email and public IP addresses### AnnotationsWe augment the original samples with the `language`, `language_score` and `token_count` annotations. The language related annotations are automatically generated by our [language filter](https://github.com/huggingface/datatrove/blob/main/src/datatrove/pipeline/filters/language_filter.py). `token_count` is generated by [applying the gpt2 tokenizer](https://github.com/huggingface/datatrove/blob/main/src/datatrove/pipeline/tokens/counter.py) to the `text` column.### Personal and Sensitive InformationWe anonymize email addresses and public IP addresses.For emails, we apply a regex pattern and replace any occurrence of an email address with either `email@example.com` or `firstname.lastname@example.org`. For IP addresses, we also employ a regex pattern and then further filter to only anonymize IP addresses [allocated for public networks](https://www.iana.org/assignments/iana-ipv4-special-registry/iana-ipv4-special-registry.xhtml). Matched IP addresses are then replaced with one of the following randomly generated IP addresses, which at the time of dataset creation were not responding to ping requests: `22.214.171.124`, `126.96.36.199`, `188.8.131.52`, `184.108.40.206`, `220.127.116.11`, and `18.104.22.168`. We decided against applying regex patterns for phone numbers due to the high false positive rate.Despite our efforts, given that 🍷 FineWeb is sourced from the internet at large, it is very likely that some personable identifiable information (PII) will be present. If you find your own PII in 🍷 FineWeb and would like it removed, please fill out our [PII removal form](https://forms.gle/VyNT3ZAUPZjPuWp39).## Considerations for Using the Data### Social Impact of DatasetWith the release of this dataset we aim to make model training more accessible to the machine learning community at large.While multiple open-weights models with strong performance have been publicly released in the past, more often than not these releases are not accompanied by the corresponding training dataset. This is unfortunate as the dataset specificities and characteristics have been demonstrated to have a very large impact and role in the performances of the models. As the creation of a high quality training dataset is a fundamental requirement to training an LLM capable of excelling at downstream tasks, with 🍷 FineWeb we (a) not only make the dataset creation process more transparent, by sharing our entire processing setup including the codebase used, we also (b) help alleviate the costs of dataset curation, both in time and in compute, for model creators by publicly releasing our dataset with the community.### Discussion of BiasesEfforts were made to minimize the amount of NSFW and toxic content present in the dataset by employing filtering on the URL level. However, there are still a significant number of documents present in the final dataset that could be considered toxic or contain harmful content. As 🍷 FineWeb was sourced from the web as a whole, any harmful biases typically present in it may be reproduced on our dataset.We deliberately avoided using machine learning filtering methods that define text quality based on the similarity to a “gold” source such as wikipedia or toxicity classifiers as these methods have been known to [disproportionately remove content in specific dialects](https://aclanthology.org/D16-1120/) and [overclassify as toxic text related to specific social identities](https://arxiv.org/pdf/2109.07445.pdf), respectively.### Other Known LimitationsAs a consequence of some of the filtering steps applied, it is likely that code content is not prevalent in our dataset. If you are training a model that should also perform code tasks, we recommend you use 🍷 FineWeb with a code dataset, such as [The Stack v2](https://huggingface.co/datasets/bigcode/the-stack-v2). You should also probably consider complementing 🍷 FineWeb with specialized curated sources (such as Wikipedia, for example) as they will likely have better formatting than the wikipedia content included in 🍷 FineWeb (we did not tailor the processing to individual websites).## Additional Information### Licensing InformationThe dataset is released under the **Open Data Commons Attribution License (ODC-By) v1.0** [license](https://opendatacommons.org/licenses/by/1-0/). The use of this dataset is also subject to [CommonCrawl's Terms of Use](https://commoncrawl.org/terms-of-use).### Future workWe plan to not only continue but also expand our efforts to create open-source high quality training datasets and to improve 🍷 FineWeb itself in future iterations.## Citation InformationPaper on [arXiv](https://arxiv.org/abs/2406.17557)```@inproceedings{penedo2024the,title={The FineWeb Datasets: Decanting the Web for the Finest Text Data at Scale},author={Guilherme Penedo and Hynek Kydl{\'\i}{\v{c}}ek and Loubna Ben allal and Anton Lozhkov and Margaret Mitchell and Colin Raffel and Leandro Von Werra and Thomas Wolf},booktitle={The Thirty-eight Conference on Neural Information Processing Systems Datasets and Benchmarks Track},year={2024},url={https://openreview.net/forum?id=n6SCkn2QaG}}```
数据集卡全文 — 31 KB · downloads: 376K · repoType: "datasets"
huggingface.co/meta-llama/Llama-3.1-8BHugging Face 实际返回的页面
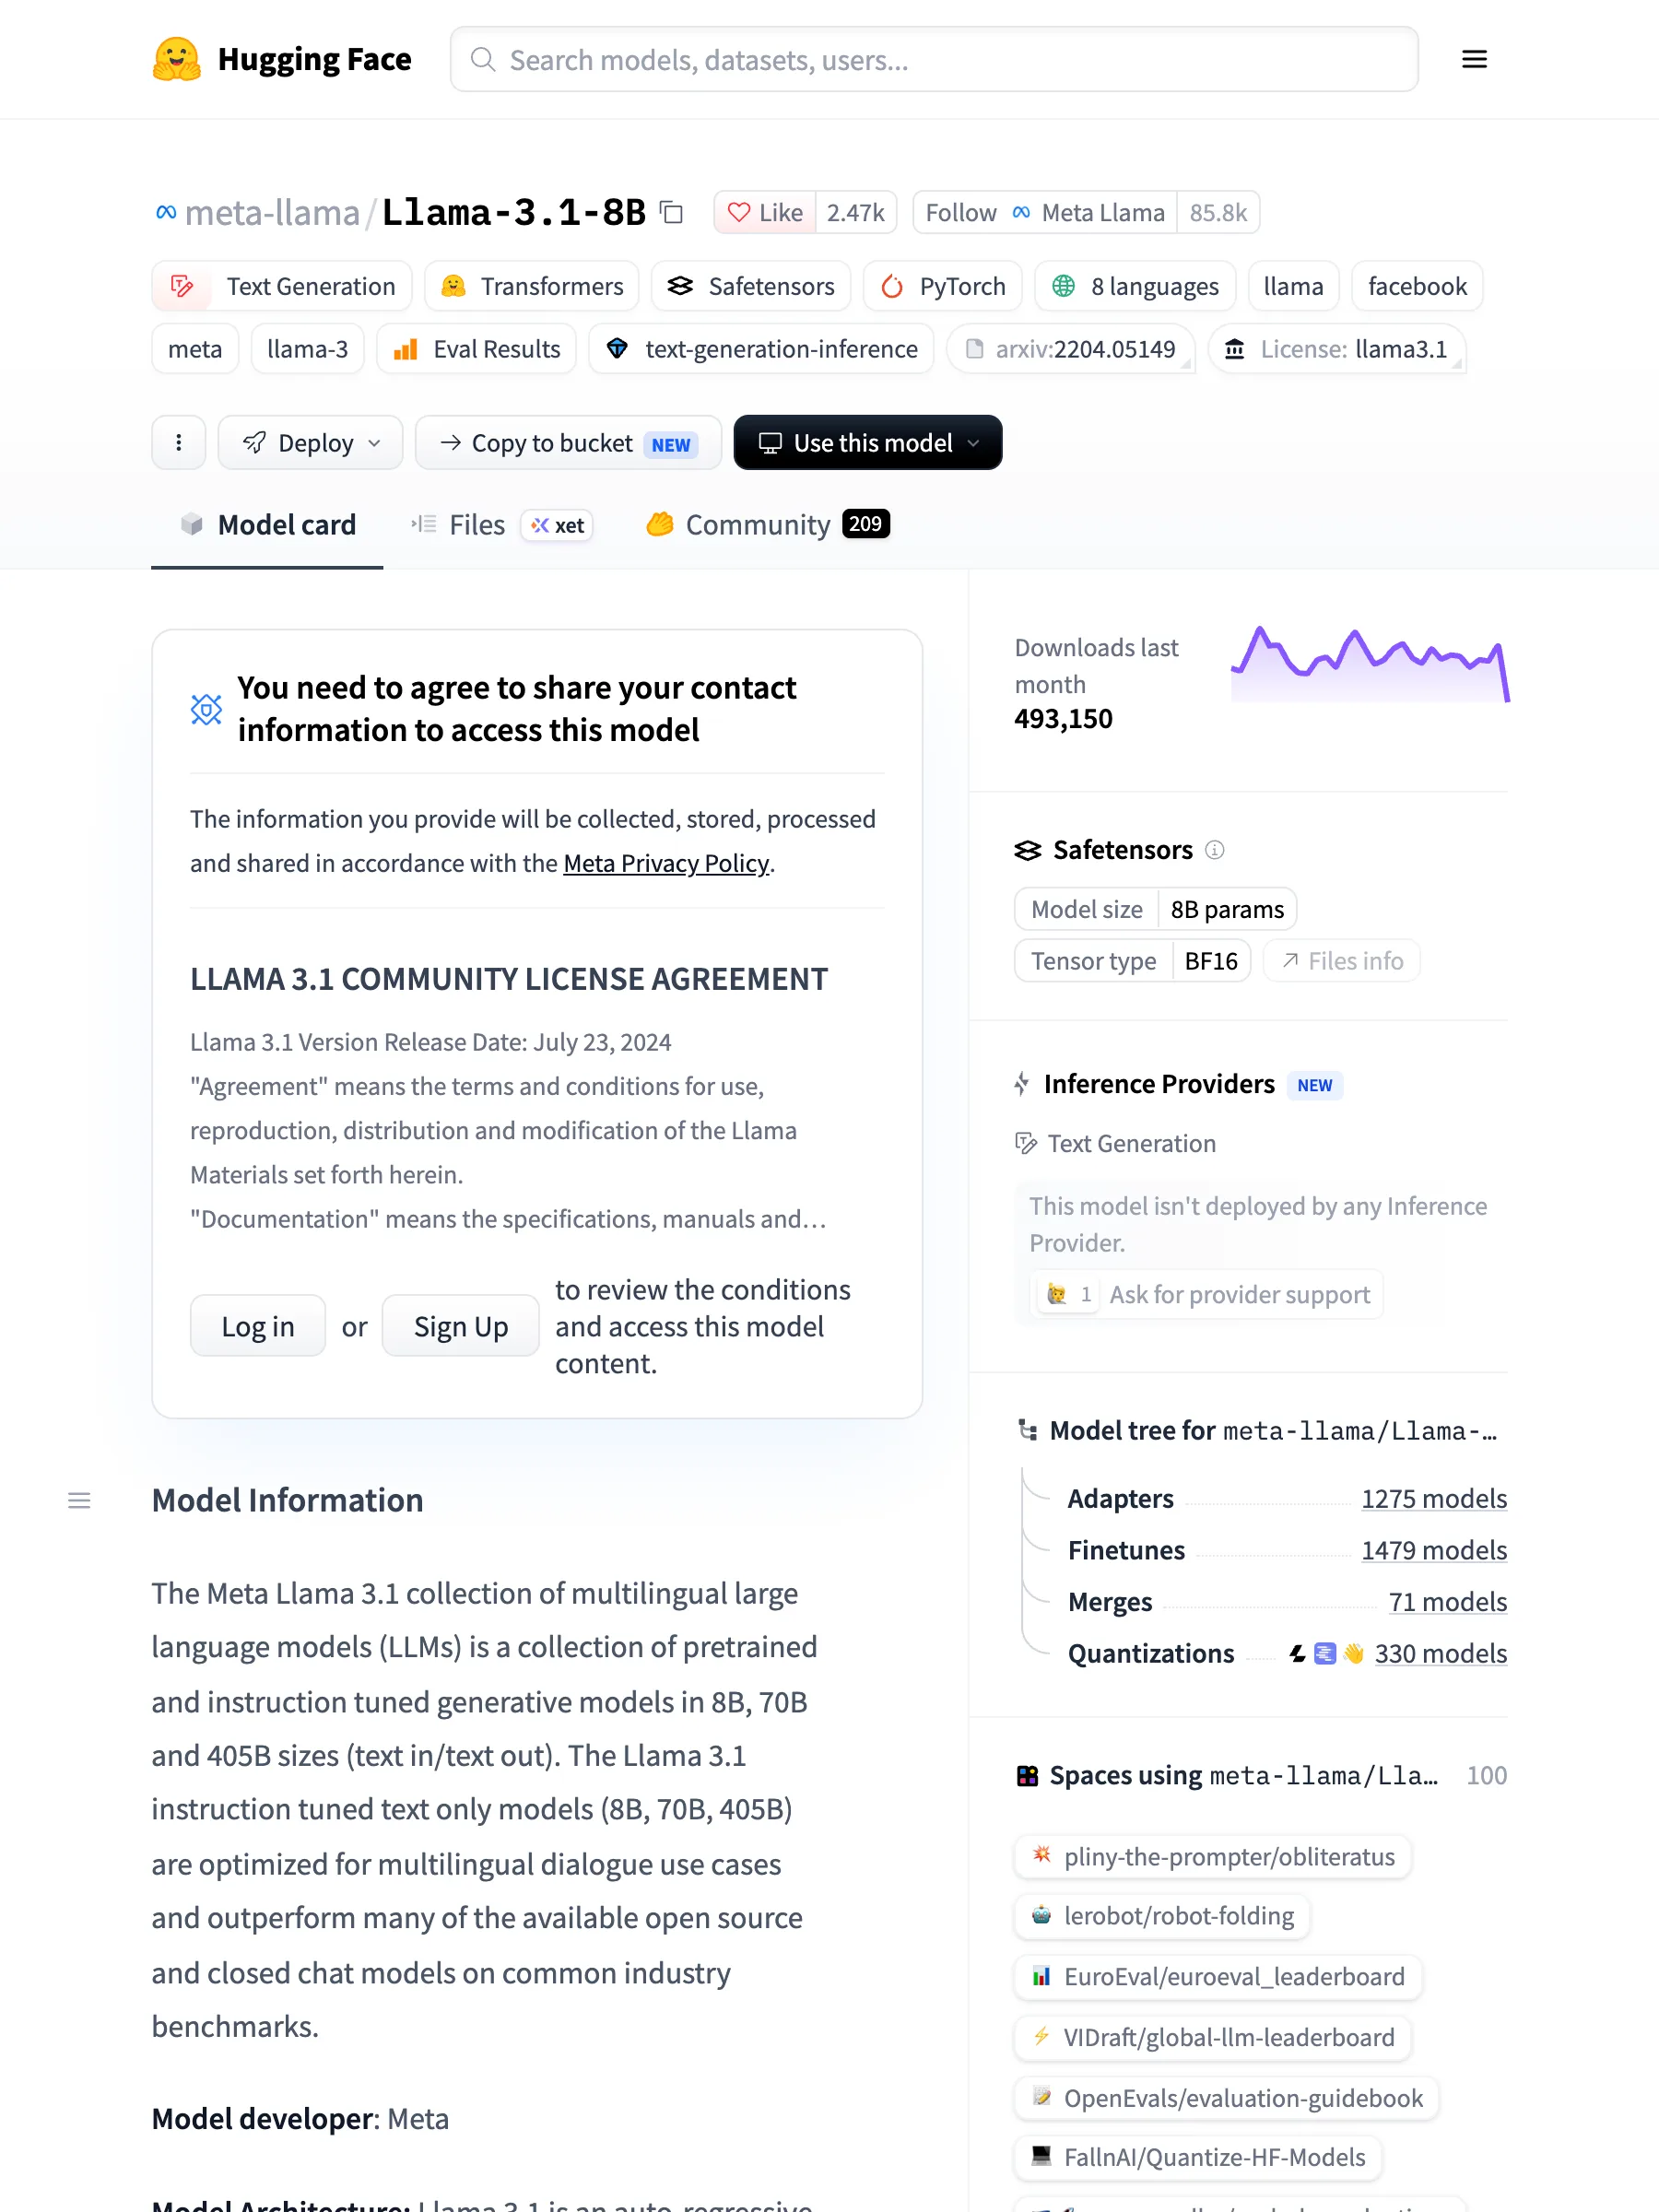
415 KB 渲染 HTML——卡片在许可协议墙内侧
API 返回的数据
markdown# meta-llama/Llama-3.1-8BType: Model · Task: text-generation · Library: transformers · License: llama3.1 · Downloads: 493,150 · Likes: 2,471 · Updated: 2024-10-16 · Gated: yesTags: transformers, safetensors, llama, text-generation, facebook, meta, pytorch, llama-3, en, de, fr, it, pt, hi, es_Model card is gated; metadata only._
metadata 卡 — 335 B · gated: true · 正文缺失如实标注
按 URL 形态划分的支持矩阵
Hugging Face 的支持是按 URL 形态实测出来的,不是按域名笼统宣称的。表里的每一行都已在生产爬虫上验证。
| URL 形态 | 状态 | 返回内容 |
|---|---|---|
/<org>/<model> | 支持 | 模型卡全文转 Markdown——README 正文加 Hub API 的标签、许可、库信息。 |
/datasets/<org>/<name> | 支持 | 同构的数据集卡——全文加 metadata 里的 downloads 和 likes。 |
/spaces/<org>/<name> | 支持 | metadata 卡——类型、许可、likes、标签。Space 没有长文卡体。 |
gated 仓库 | 仅 metadata | gated 模型和数据集返回带 gated: true 与明示备注的 metadata——卡体需要任何人都无法伪造的许可同意。 |
绕过 SPA 壳直接拿模型卡
Hugging Face 页面是包着卡片的 JavaScript 壳。把仓库 URL 发给 Crawl 接口,请求会路由到专用适配器——调公开 Hub API 加仓库 raw README,卡片以 Markdown 返回,downloads、likes、pipeline 标签进结构化 metadata。
API 加 raw 卡二合一
适配器合并 Hub API 记录和仓库 raw README——结构化字段和作者写的卡正文一次返回。
gated 就是 gated
gated 仓库返回带 gated: true 和「卡片已 gated」明示备注的公开 metadata——管线拿到事实,而不是去刮协议墙。
结构化 metadata 做路由
results.metadata 带 repoType、pipelineTag、library、downloads、likes——按字段分支,不用解析卡文。
按 URL 形态实测
矩阵每行都是真实 URL 在线爬虫的复现结果——按形态实测,不按域名拍胸脯。
什么是 Hugging Face 抓取 API?
Hugging Face 抓取 API 是一个 HTTP 接口:传入 Hugging Face URL,返回结构化、模型可用的仓库卡片。网页是 SPA 壳,实质是 README 卡加 Hub metadata 记录。Search1API 的 Crawl 接口直接读两者——downloads、likes、pipeline 标签等字段走公开 Hub API,作者写的卡体走仓库 raw 文件——模型、数据集、Space 的卡片不渲染页面就能拿到 Markdown。
典型工作流
把 Hugging Face URL 发给 Crawl 接口,拿回结构化 Markdown——模型和数据集卡全文、Space 的 metadata 卡、gated 仓库的诚实部分结果。无需账号。
把 Hugging Face URL POST 给 Crawl 接口——不需要账号。
URL 按形态规则匹配,路由到 Hugging Face 适配器。
卡片以 Markdown + results.metadata 返回——repoType、pipelineTag、downloads、likes、gated。
gated 仓库返回带明示备注的 metadata 卡——边界被命名,不被隐藏。
典型用法
索引模型和数据集卡做内部发现——downloads 和 likes 以可排序字段到达。
跟踪模型家族——卡片加 metadata 一次调用说清任务、库、许可。
申请访问前先筛 gated 仓库——metadata 卡不穿墙就给出许可和统计。
喂给按 pipelineTag 和 library 分支的评测管线——不用解析散文。
常见问题
需要 Hugging Face 账号或 token 吗?
不需要。适配器读公开 Hub API 端点和 raw 仓库文件——读取路径上没有 token。gated 仓库返回公开 metadata 和显式 gated 标记。
支持哪些 Hugging Face URL?
模型页(/<org>/<model>)、数据集页(/datasets/<org>/<name>)、Space 页(/spaces/<org>/<name>)。Space 没有长文卡体,返回 metadata 卡。
Llama 这类 gated 模型会返回什么?
metadata 卡——类型、任务、库、许可、downloads、likes、标签,带 gated: true 和「卡体已 gated」备注。卡体需要接受许可协议,任何读取路径都无法伪造。
和 huggingface.co/api 有什么区别?
就是那个 API 加上卡片。适配器把 Hub 记录和仓库 raw README 合并成一个 Markdown + metadata 响应——两调用变一调用,也不用写字段映射。
返回哪些 metadata?
platform、repoType(models/datasets/spaces)、repoId、pipelineTag、library、downloads、likes、gated、readmeSource——不读卡也能路由或排序。
抓 Hugging Face 合法吗?
我们只取 Hugging Face 通过公开 API 和 raw 文件匿名提供的内容——不登录、不共享会话、不绕过访问控制。具体用途是否合法取决于你的法域和场景,请与自己的法务确认。