Bilibili scraper API for video pages
Send a Bilibili video URL — or a b23.tv short link — to the Crawl endpoint and get back a structured card: title, description, and engagement stats. Verified for /video/ pages, honest about what is not covered.
Endpoint — bash
A dedicated parser extracts the video card — the metadata block Bilibili publishes alongside the player.
The video title and the full uploader-written description as Markdown.
Views, likes, comments, favorites, and coins in results.metadata.stats.
b23.tv mobile share links are followed to the canonical video page automatically.
Useful for
Chinese video content monitoring / Uptake analytics per video / RAG over video metadata
What goes in, what comes back
Two real anonymous captures — a video page and a b23.tv short link. Left: the page as Bilibili serves it to logged-out viewers. Right: the complete results.content the API returns, byte for byte.
bilibili.com/video/BV1DJYe6AEgPWhat Bilibili serves
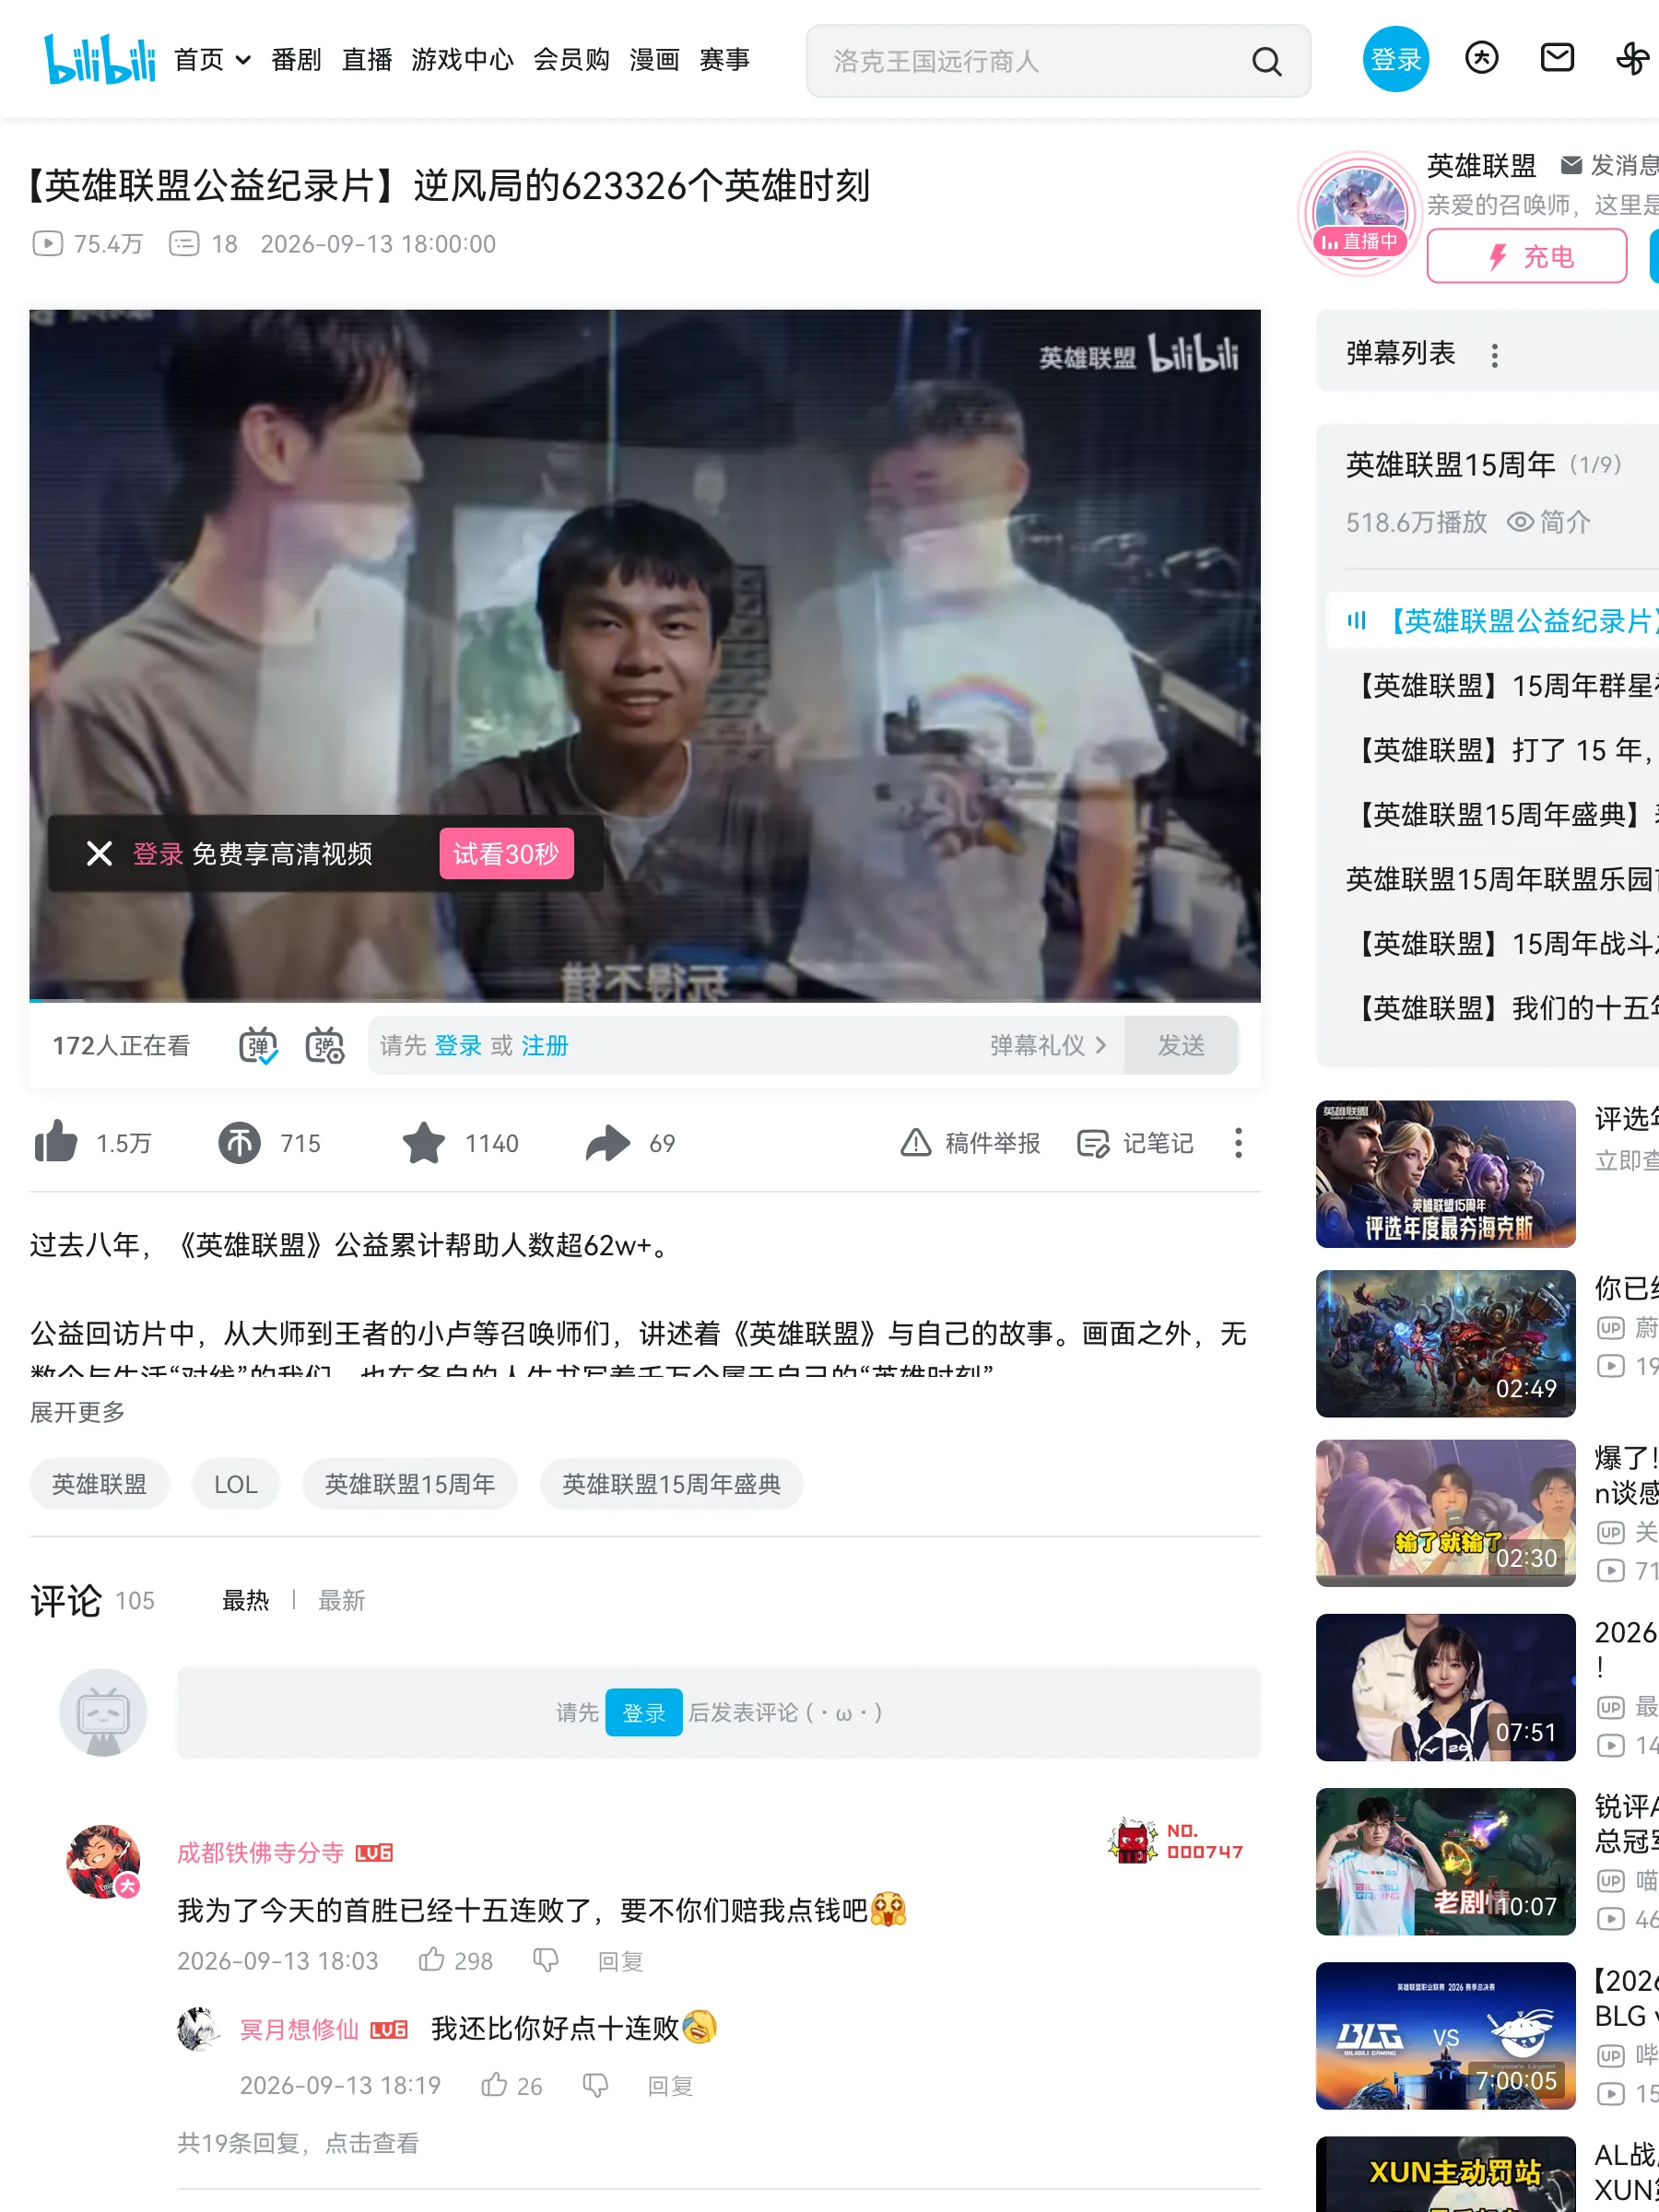
Full app shell — player, danmaku rail, recommendations, comments
What the API returns
markdown
Title + description + stats card — 293 bytes · availability: partial
b23.tv/BV1PeYe69EWkWhat Bilibili serves
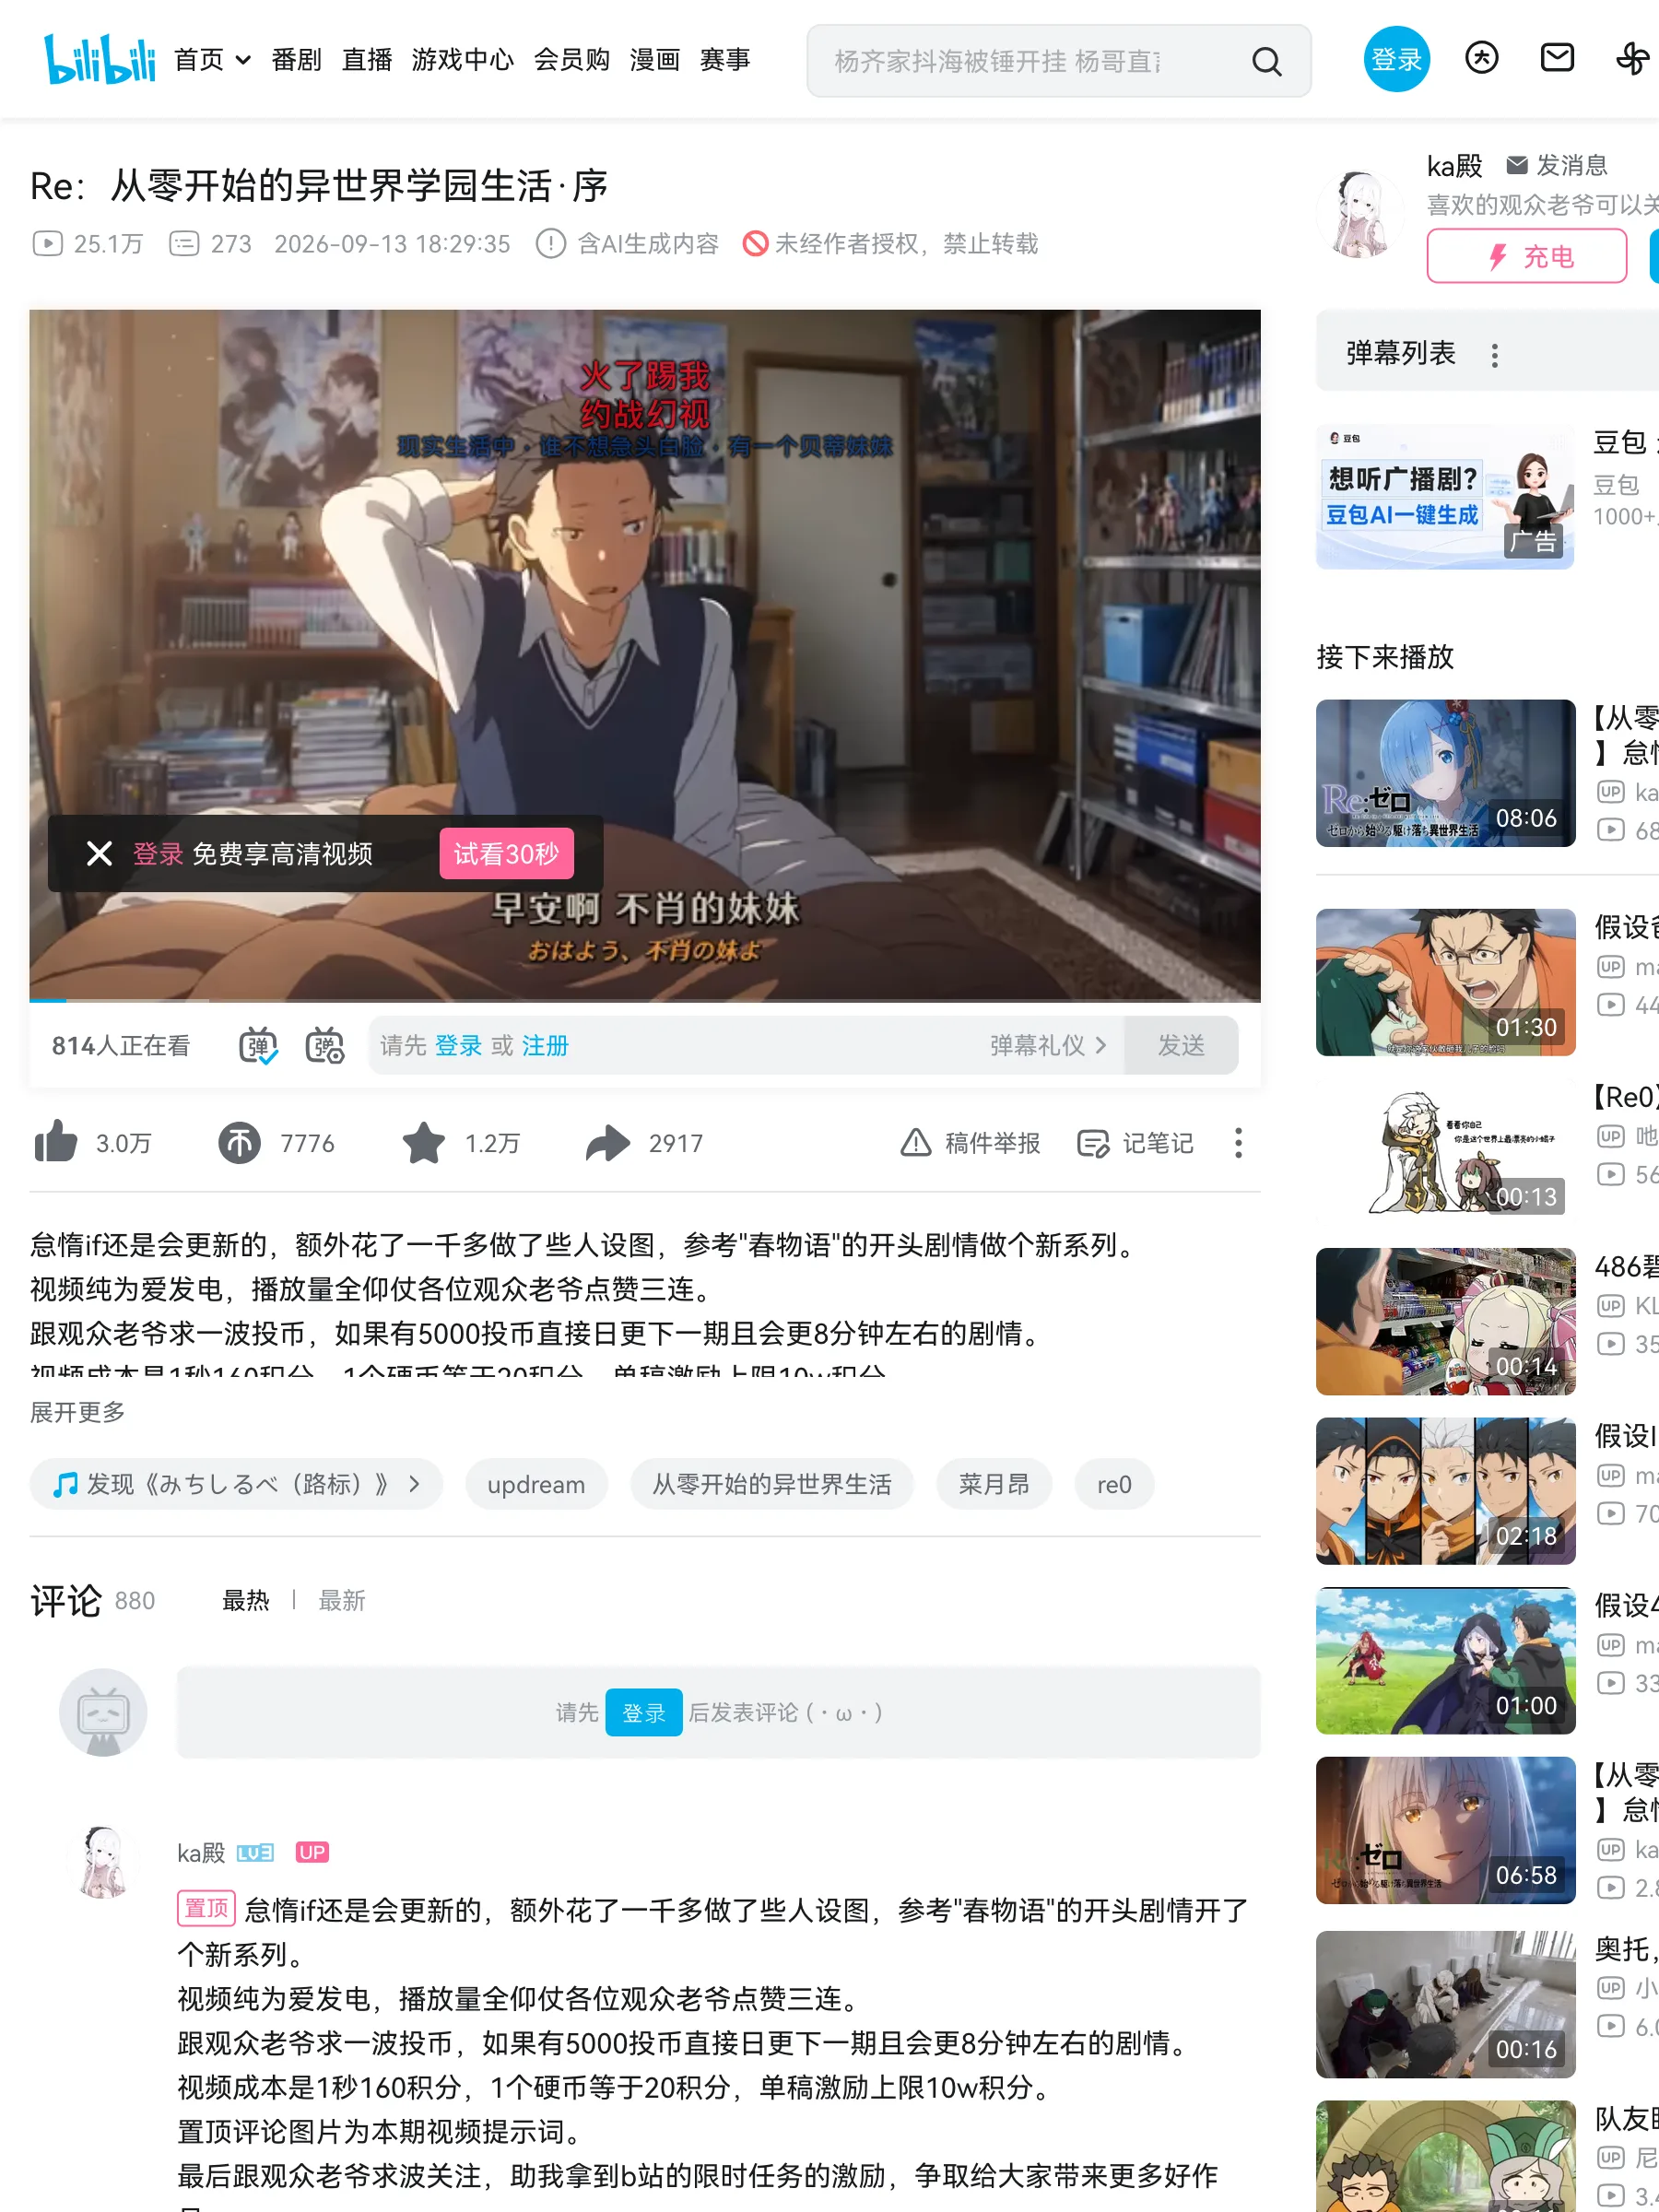
b23.tv/<code> resolves to the canonical /video/ page on its own
What the API returns
markdown
Same card for the resolved video — stats fields identical shape
What is covered, by URL pattern
Bilibili support is measured per URL pattern, not claimed per domain. Every row below is verified against the live crawler.
| URL pattern | Status | What you get |
|---|---|---|
bilibili.com/video/BV<id> | Supported | Title, description, and stats — views, likes, comments, favorites, coins. Output is marked availability: "partial" because publishedTime is not exposed on this path. |
b23.tv/<code> | Supported | Short links resolve to the target video page and return the same structured card — the standard mobile share format. |
bangumi / read / opus / space / live | Not covered | Episodes, column articles, dynamic posts, uploader spaces, and live rooms currently fail content-quality validation — tested and excluded rather than claimed. |
The video card, without the player shell
A Bilibili video page is a heavy application shell — player, danmaku rail, recommendations, comments. Point the Crawl endpoint at a /video/ URL and the dedicated parser returns the metadata card underneath: title, the uploader-written description, and the five engagement counters.
Structured stats, not screen-scraped text
Views, likes, comments, favorites, and coins arrive as numbers in results.metadata.stats — ready for analytics without regex.
Short links included
b23.tv is how Bilibili links travel on mobile. The crawler follows the redirect and parses the resolved video page.
Honest availability flags
The parser marks the card availability: "partial" and lists unavailableFields — publishedTime is not exposed on this path, and the output says so instead of inventing a date.
Verified per URL pattern
Every matrix row is reproduced from a live crawl of a real URL — video and short links are covered, other page types are tested and marked out of scope.
What is a Bilibili scraper API?
A Bilibili scraper API is an HTTP interface that takes a bilibili.com video URL — or a b23.tv short link — and returns the video metadata in a structured, model-ready format. Bilibili is one of the largest video communities in Chinese, but the page is built for playback, not extraction. Search1API’s Crawl endpoint routes these URLs to a dedicated parser that emits the title, description, and engagement counters as a compact card — and reports partial availability instead of fabricating missing fields.
Typical workflow
Send a Bilibili video URL — or a b23.tv short link — to the Crawl endpoint and get back a structured card: title, description, and engagement stats. Verified for /video/ pages, honest about what is not covered.
POST a bilibili.com/video/BV… URL — or a b23.tv short link — to the Crawl endpoint.
The URL is matched against the pattern rules and routed to the dedicated Bilibili parser.
The video card returns as Markdown plus results.metadata.stats — views, likes, comments, favorites, coins.
Check availability and unavailableFields before relying on fields like publishedTime.
Where teams use it
Monitor video performance — the five engagement counters update on every crawl.
Feed Chinese video metadata into RAG and recommendation pipelines.
Resolve b23.tv share links from chat exports back to canonical video pages.
Track topic spread — titles and descriptions arrive as clean text for clustering.
FAQ
Which Bilibili URLs are supported?
Video pages — bilibili.com/video/BV<id> — and b23.tv short links that resolve to one. Bangumi episodes, column articles, dynamic posts, spaces, and live rooms were tested and are not covered today.
What does availability: "partial" mean?
The card returns title, description, and stats, but publishedTime is not exposed on this path. The output declares that in unavailableFields instead of guessing a date — check the flag before piping fields downstream.
Does the video itself get transcribed?
No — the parser returns the metadata card: title, uploader description, and engagement stats. Video content and danmaku are out of scope.
What happens with a deleted video?
Bilibili serves a "视频去哪了呢?" placeholder page — the parser returns that placeholder text, so validate results before treating output as a real video card.
Do I need a Bilibili account?
No — public video pages are served to anonymous viewers, and the parser reads the same page. Login-required content stays out of scope.
Is scraping Bilibili legal?
We only fetch pages Bilibili serves to anonymous visitors — no login, no session sharing, no circumvention of access controls. Whether a specific use complies with applicable law and platform terms depends on your jurisdiction and use case, so confirm that with your own counsel.