YouTube public pages to Markdown

YouTube scraper API for transcripts and playlists

Send a public YouTube URL to the Crawl endpoint and get back structured Markdown — timestamped transcripts for videos, structured entries for playlists. No Google account needed.

Endpointbash
POST https://api.search1api.com/crawl
{ "url": "https://www.youtube.com/watch?v=aircAruvnKk" }
What you can crawl

The parser reads the caption track YouTube embeds in the page — no headless video processing.

1
Videos

Full transcript with timestamps, plus videoId and availability flags in metadata.

2
Playlists

Playlist title and description plus a structured entry per video — title, channel, duration.

3
Caption coverage

Videos without captions come back as honest partials — availability and unavailableFields say exactly what is missing.

Useful for

RAG over lectures / Subtitle datasets / Playlist inventories

What goes in, what comes back

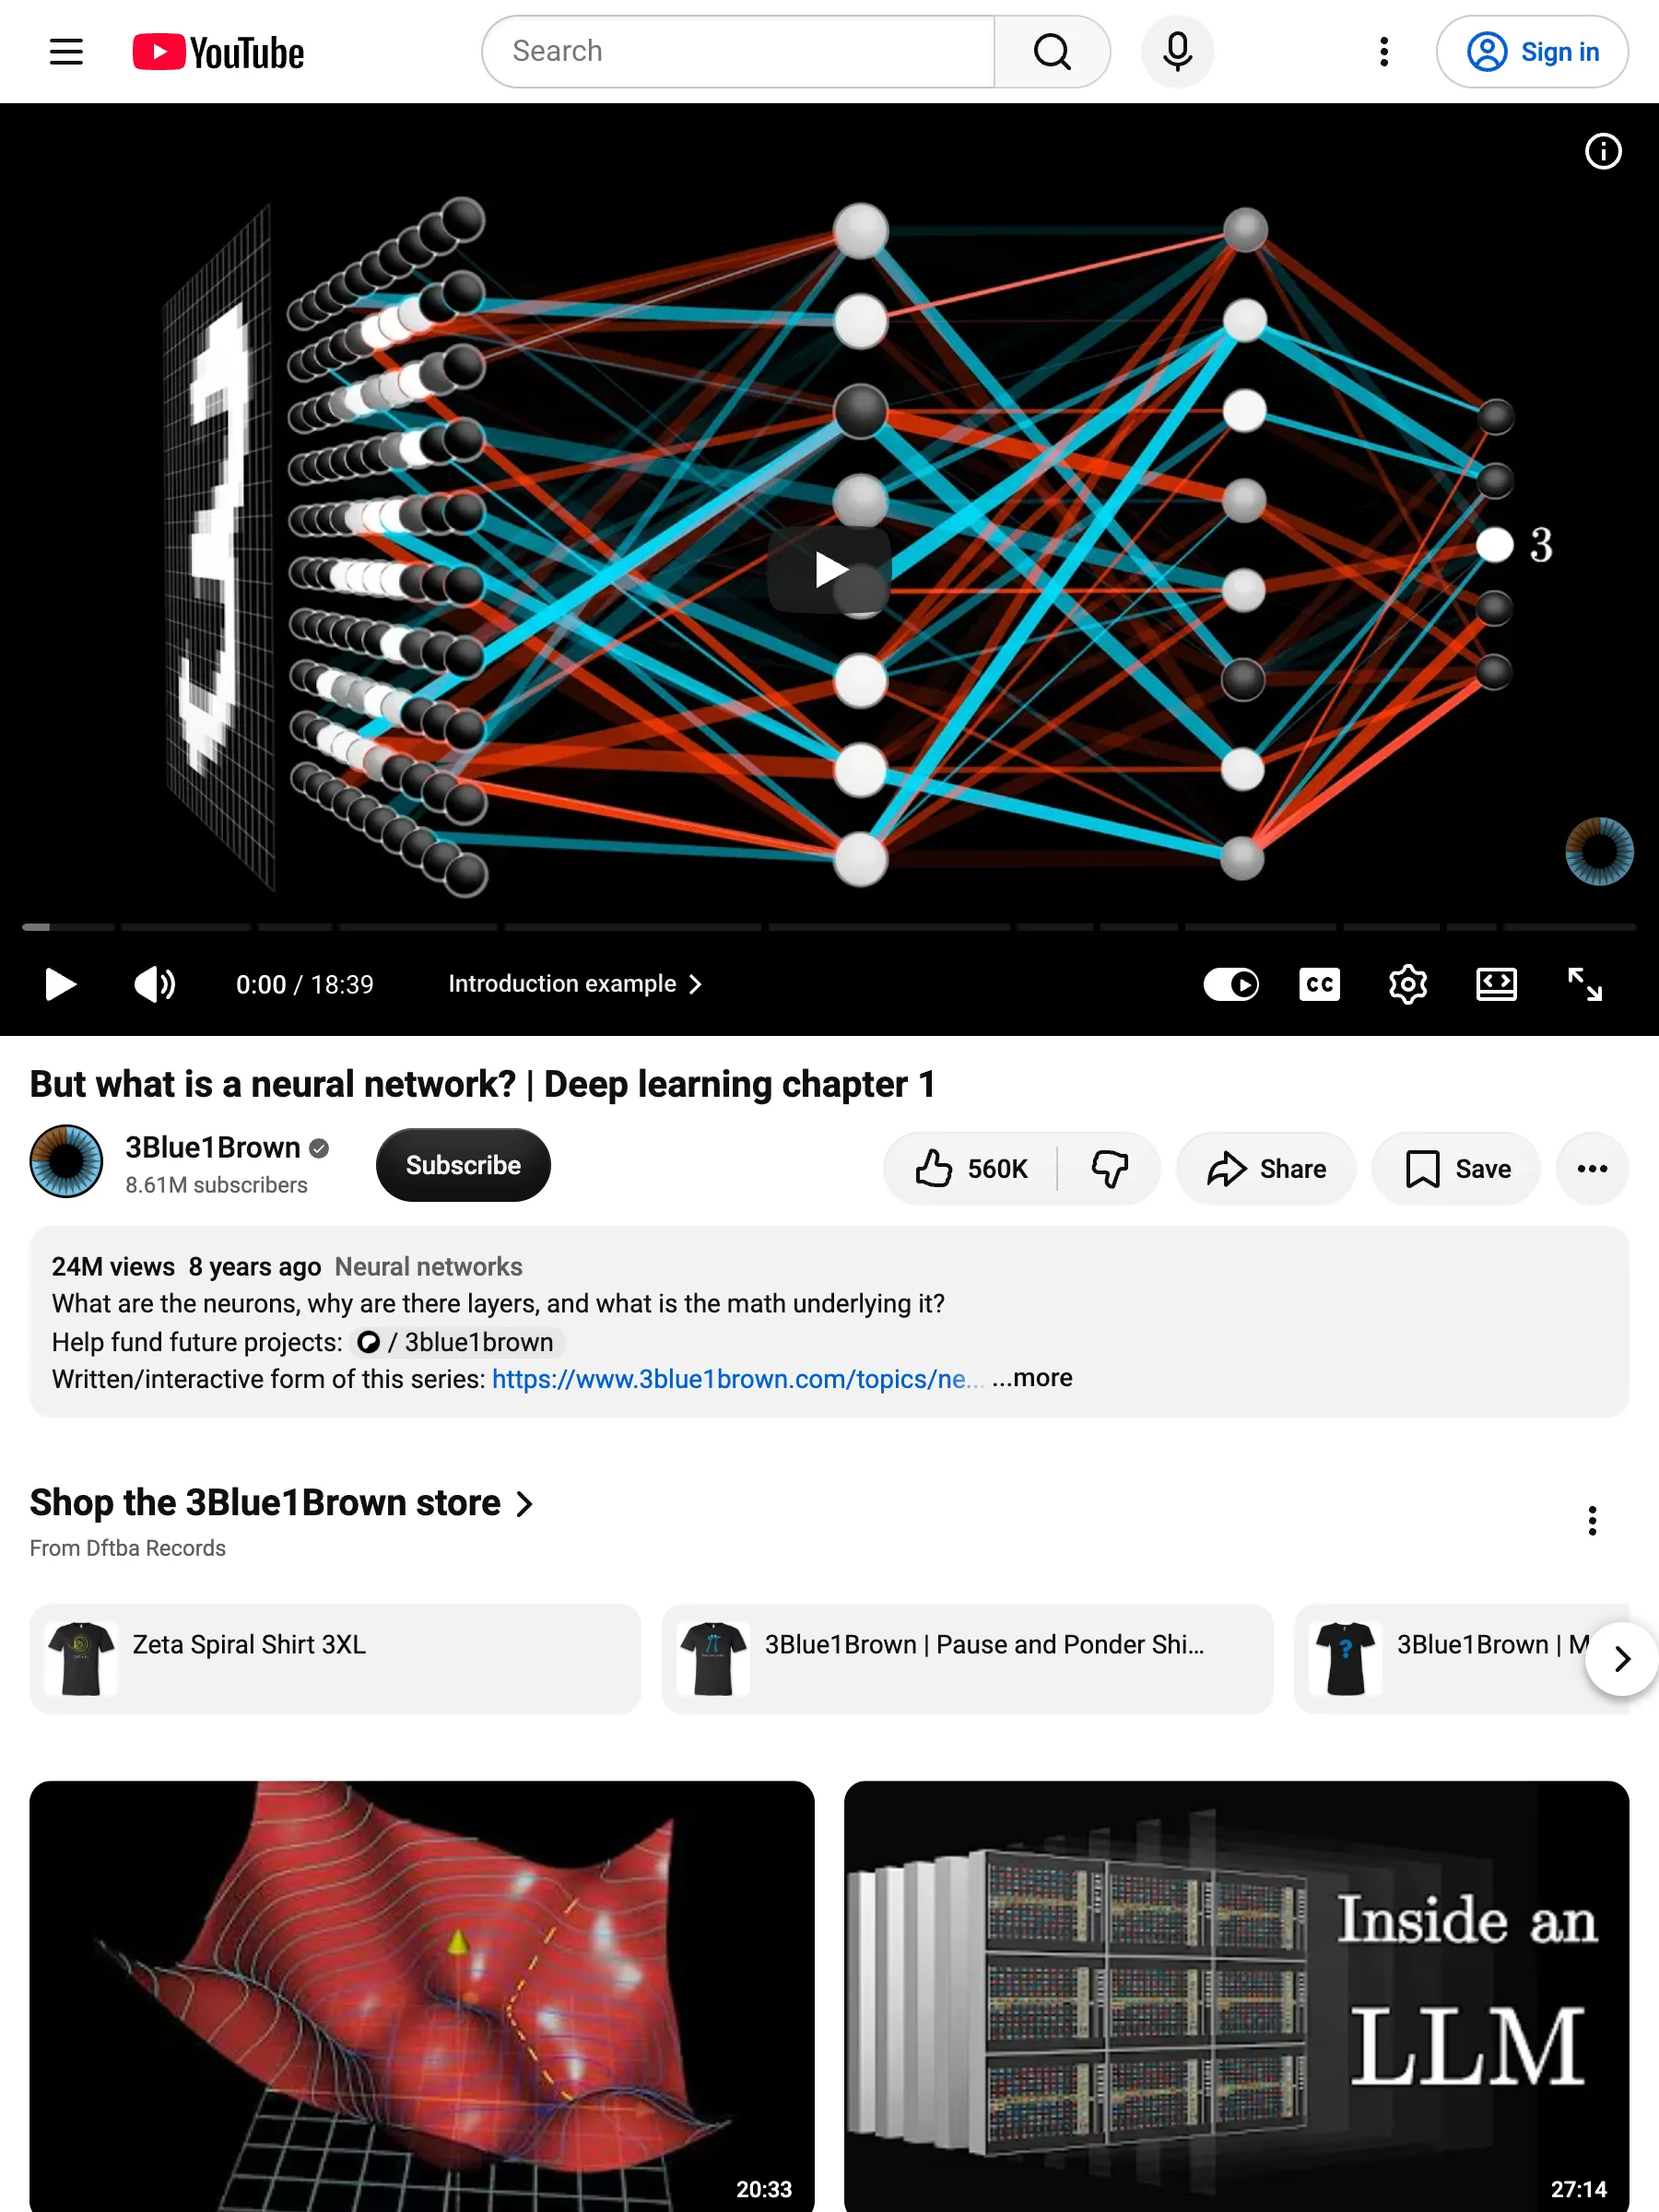
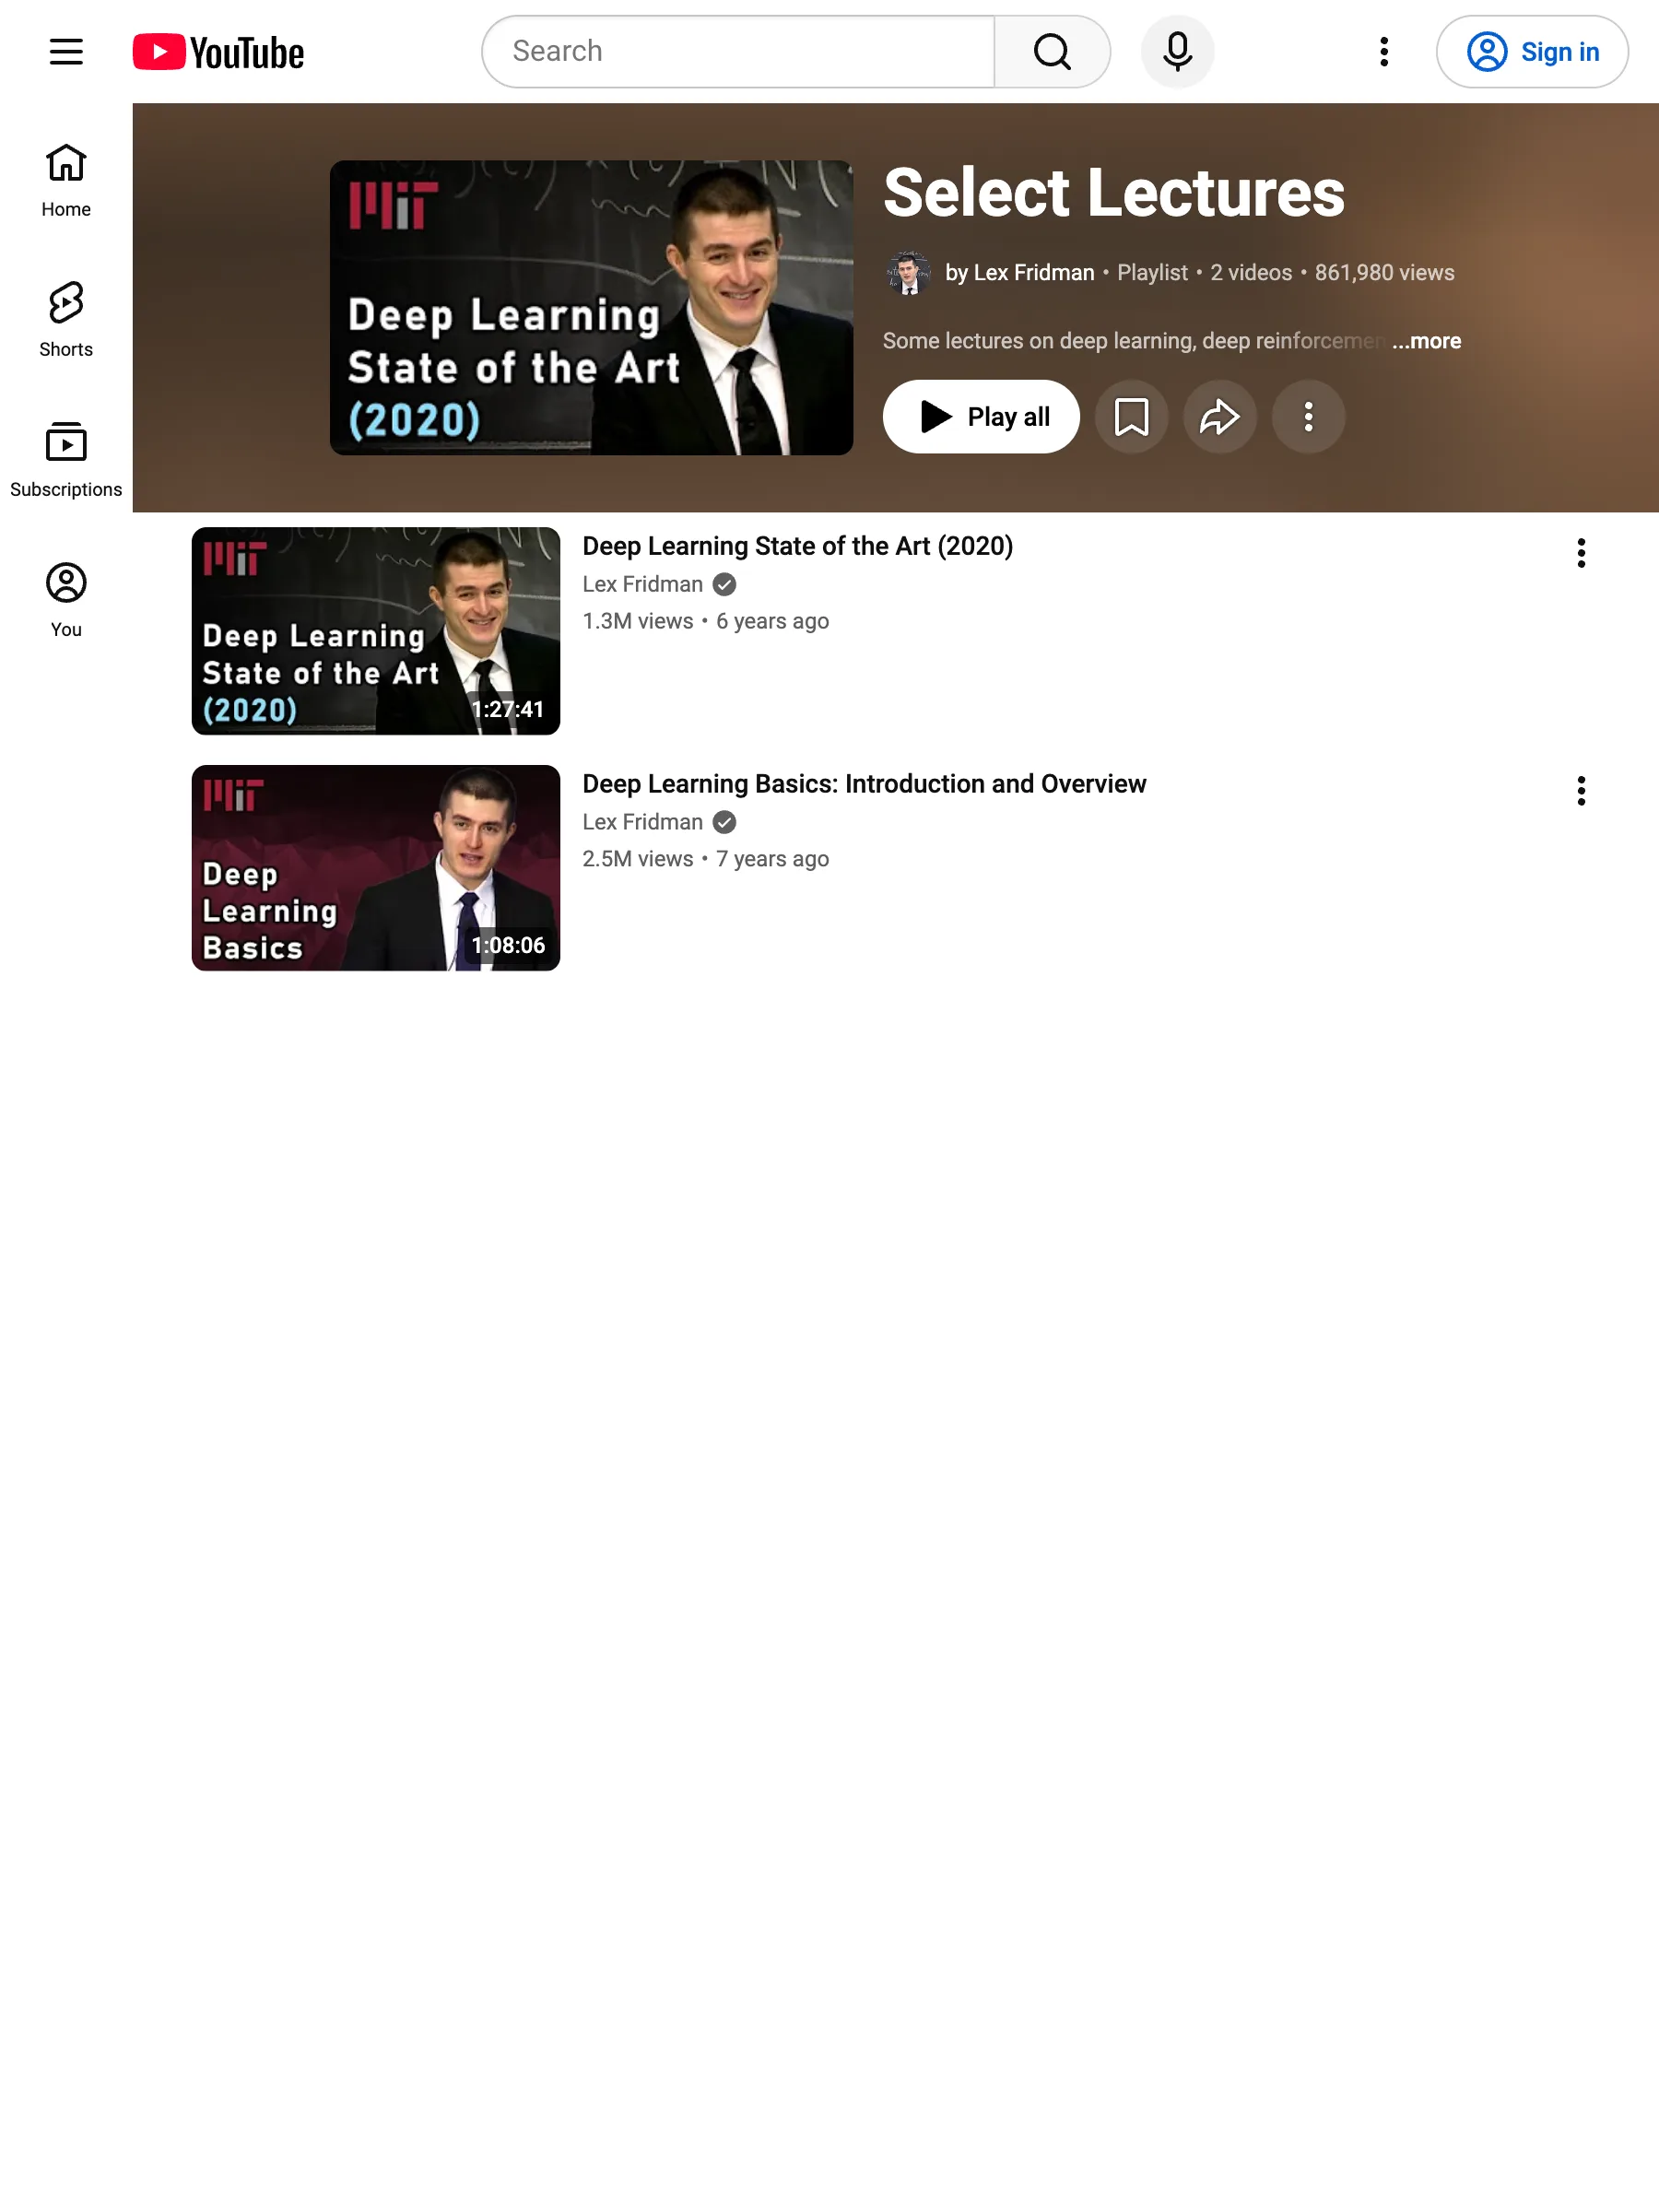
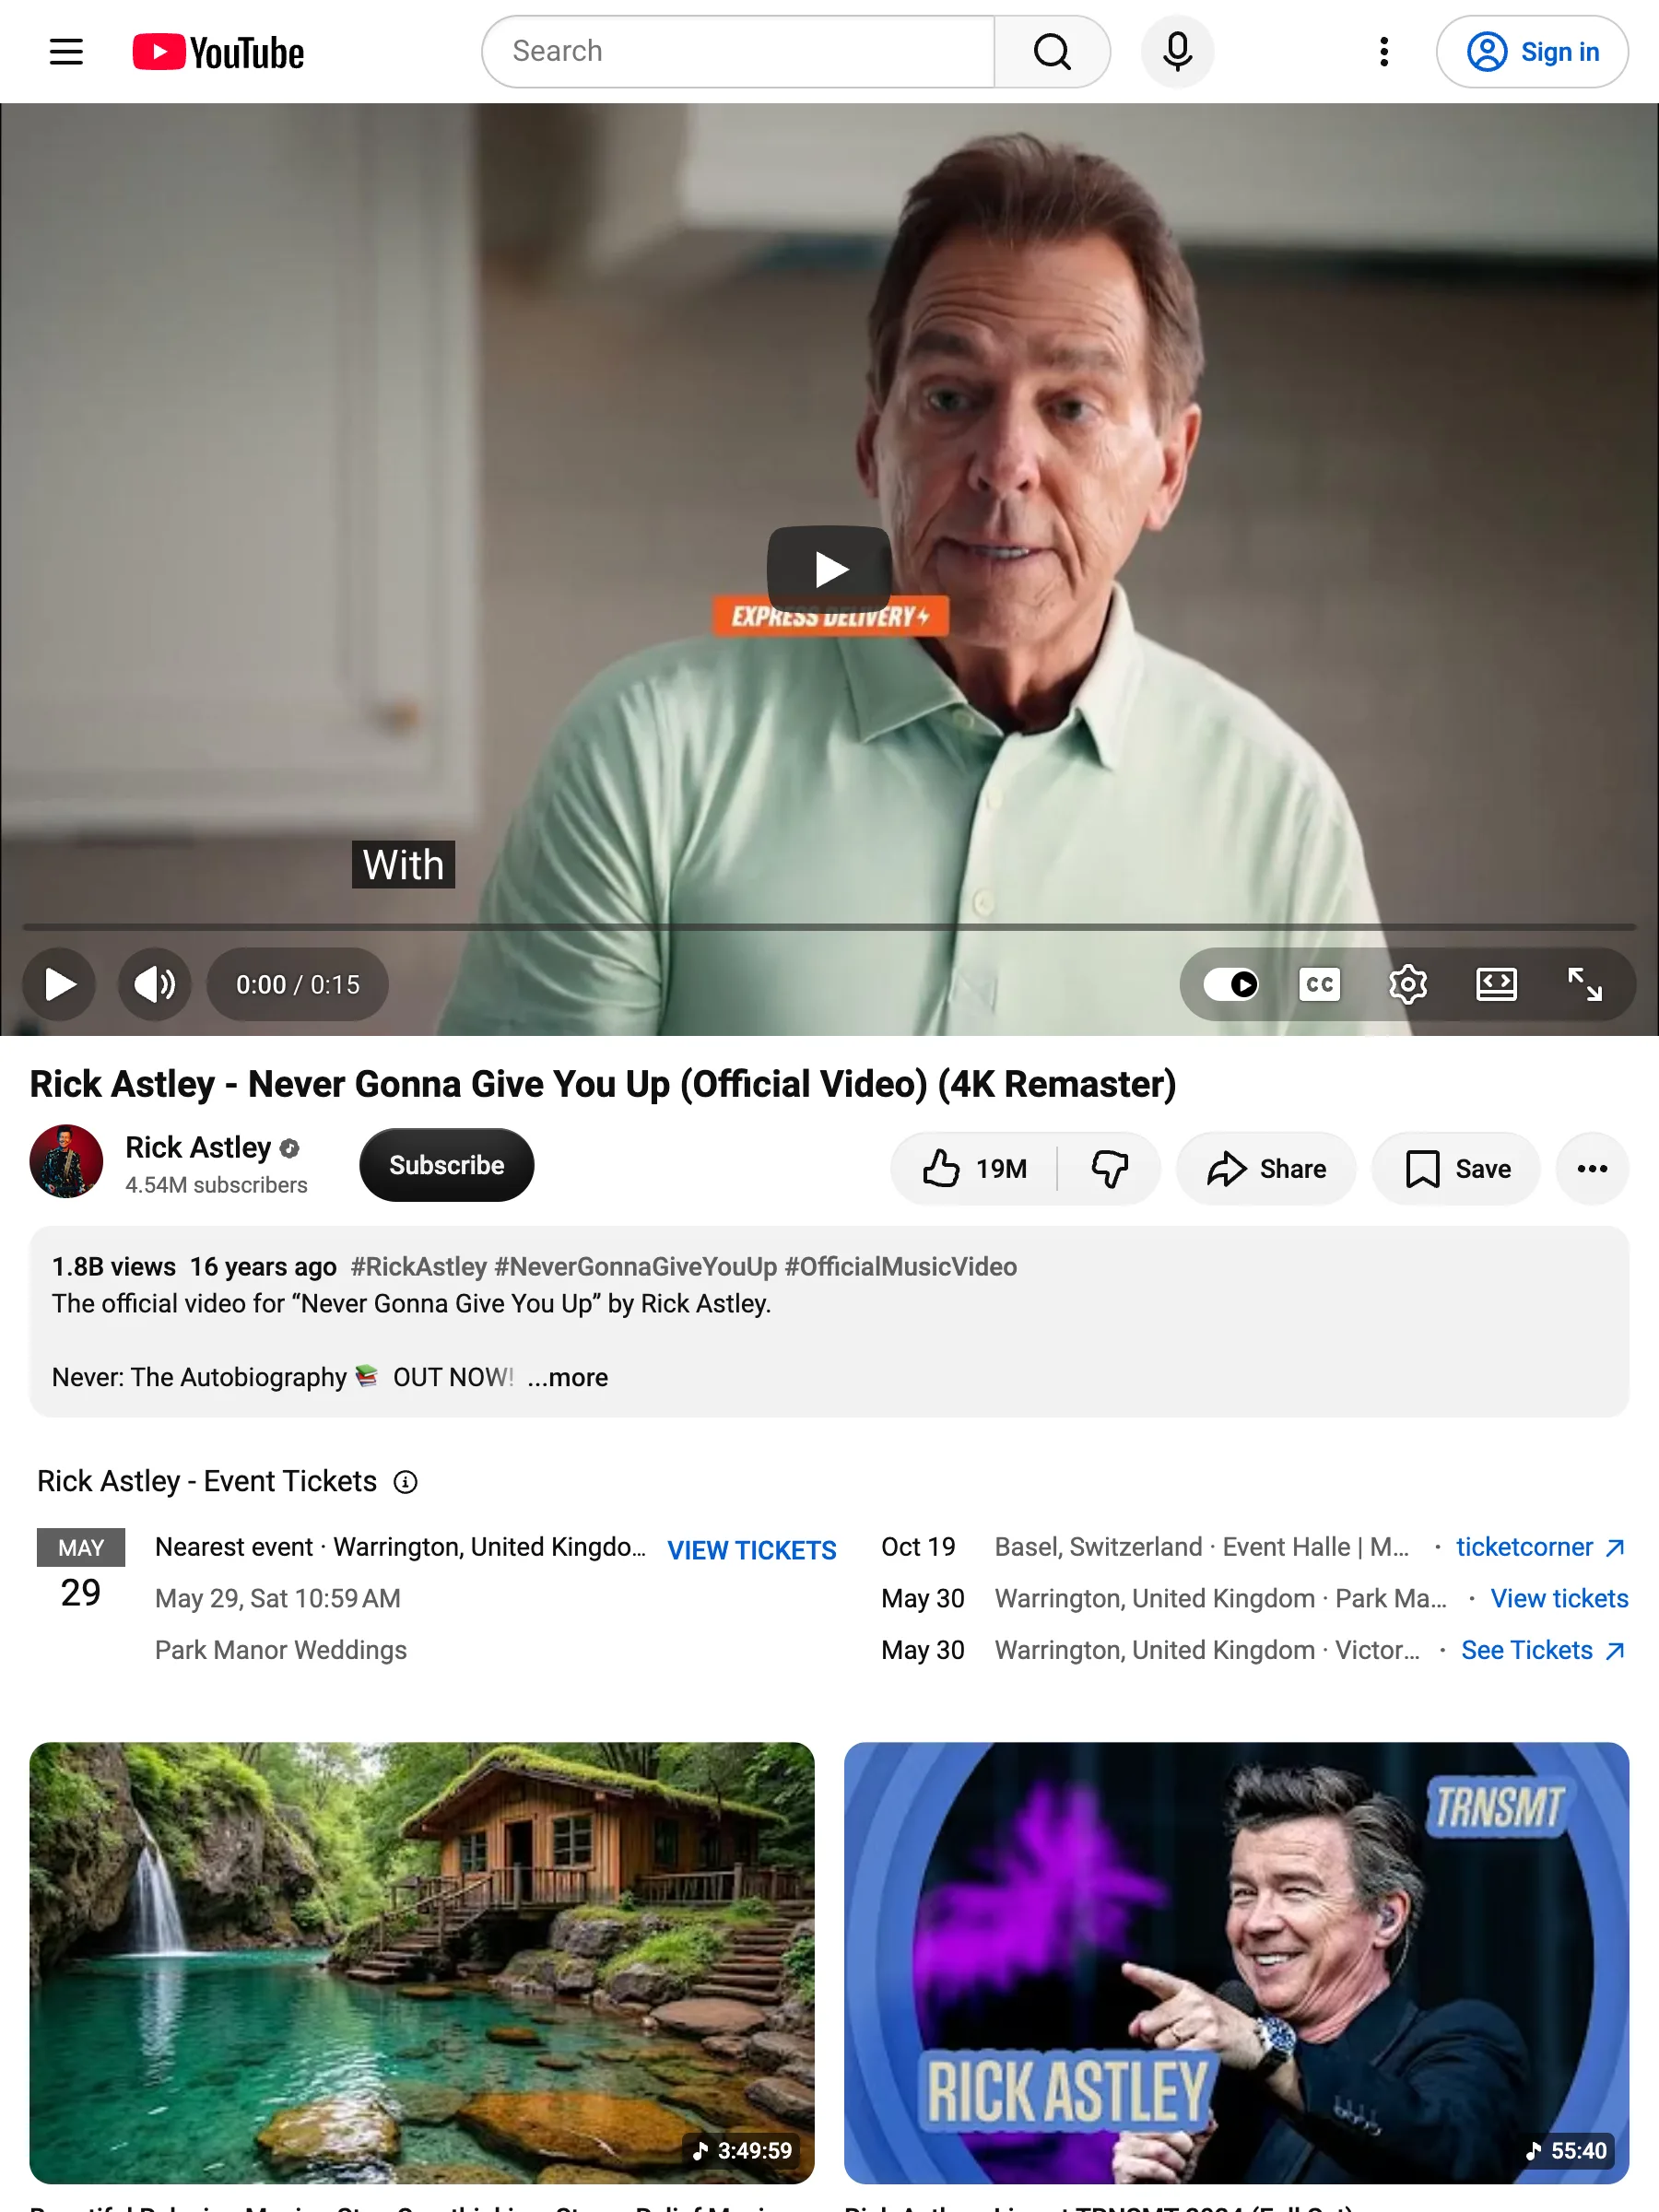
Three URL types. Left: the public page as YouTube actually serves it to anonymous visitors — a real capture through the same egress the crawler uses. Right: the complete results.content the API returns, byte for byte.

Video + transcriptyoutube.com/watch?v=aircAruvnKk

What YouTube serves

3Blue1Brown neural network video on YouTube as served to anonymous visitors

2.5 MB of rendered HTML — player shell, recommendations, store modules

What the API returns

markdown
## Transcript
### Introduction example
**0:04** · This is a 3.
**0:06** · It's sloppily written and rendered at an extremely low resolution of 28x28 pixels, but your brain has no trouble recognizing it as a 3.
**0:14** · And I want you to take a moment to appreciate how crazy it is that brains can do this so effortlessly.
**0:19** · I mean, this, this and this are also recognizable as 3s, even though the specific values of each pixel is very different from one image to the next.
**0:28** · The particular light-sensitive cells in your eye that are firing when you see this 3 are very different from the ones firing when you see this 3.
**0:37** · But something in that crazy-smart visual cortex of yours resolves these as representing the same idea, while at the same time recognizing other images as their own distinct ideas.
**0:49** · But if I told you, hey, sit down and write for me a program that takes in a grid of 28x28 pixels like this and outputs a single number between 0 and 10, telling you what it thinks the digit is, well the task goes from comically trivial to dauntingly difficult.
### Series preview
**1:07** · Unless you've been living under a rock, I think I hardly need to motivate the relevance and importance of machine learning and neural networks to the present and to the future.
**1:15** · But what I want to do here is show you what a neural network actually is, assuming no background, and to help visualize what it's doing, not as a buzzword but as a piece of math.
**1:25** · My hope is that you come away feeling like the structure itself is motivated, and to feel like you know what it means when you read, or you hear about a neural network quote-unquote learning.
**1:35** · This video is just going to be devoted to the structure component of that, and the following one is going to tackle learning.
**1:40** · What we're going to do is put together a neural network that can learn to recognize handwritten digits.
**1:49** · This is a somewhat classic example for introducing the topic, and I'm happy to stick with the status quo here, because at the end of the two videos I want to point you to a couple good resources where you can learn more, and where you can download the code that does this and play with it on your own computer.
**2:05** · There are many many variants of neural networks, and in recent years there's been sort of a boom in research towards these variants, but in these two introductory videos you and I are just going to look at the simplest plain vanilla form with no added frills.
**2:19** · This is kind of a necessary prerequisite for understanding any of the more powerful modern variants, and trust me it still has plenty of complexity for us to wrap our minds around.
**2:29** · But even in this simplest form it can learn to recognize handwritten digits, which is a pretty cool thing for a computer to be able to do.
**2:37** · And at the same time you'll see how it does fall short of a couple hopes that we might have for it.
### What are neurons?
**2:43** · As the name suggests neural networks are inspired by the brain, but let's break that down.
**2:48** · What are the neurons, and in what sense are they linked together?
**2:52** · Right now when I say neuron all I want you to think about is a thing that holds a number, specifically a number between 0 and 1.
**3:00** · It's really not more than that.
**3:03** · For example the network starts with a bunch of neurons corresponding to each of the 28x28 pixels of the input image, which is 784 neurons in total.
**3:14** · Each one of these holds a number that represents the grayscale value of the corresponding pixel, ranging from 0 for black pixels up to 1 for white pixels.
**3:25** · This number inside the neuron is called its activation, and the image you might have in mind here is that each neuron is lit up when its activation is a high number.
### Introducing layers
**3:36** · So all of these 784 neurons make up the first layer of our network.
**3:46** · Now jumping over to the last layer, this has 10 neurons, each representing one of the digits.
**3:52** · The activation in these neurons, again some number that's between 0 and 1, represents how much the system thinks that a given image corresponds with a given digit.
**4:03** · There's also a couple layers in between called the hidden layers, which for the time being should just be a giant question mark for how on earth this process of recognizing digits is going to be handled.
**4:14** · In this network I chose two hidden layers, each one with 16 neurons, and admittedly that's kind of an arbitrary choice.
**4:21** · To be honest I chose two layers based on how I want to motivate the structure in just a moment, and 16, well that was just a nice number to fit on the screen.
**4:28** · In practice there is a lot of room for experiment with a specific structure here.
**4:33** · The way the network operates, activations in one layer determine the activations of the next layer.
**4:39** · And of course the heart of the network as an information processing mechanism comes down to exactly how those activations from one layer bring about activations in the next layer.
**4:49** · It's meant to be loosely analogous to how in biological networks of neurons, some groups of neurons firing cause certain others to fire.
**4:58** · Now the network I'm showing here has already been trained to recognize digits, and let me show you what I mean by that.
**5:03** · It means if you feed in an image, lighting up all 784 neurons of the input layer according to the brightness of each pixel in the image, that pattern of activations causes some very specific pattern in the next layer which causes some pattern in the one after it, which finally gives some pattern in the output layer.
**5:22** · And the brightest neuron of that output layer is the network's choice, so to speak, for what digit this image represents.
### Why layers?
**5:32** · And before jumping into the math for how one layer influences the next, or how training works, let's just talk about why it's even reasonable to expect a layered structure like this to behave intelligently.
**5:44** · What are we expecting here?
**5:45** · What is the best hope for what those middle layers might be doing?
**5:48** · Well, when you or I recognize digits, we piece together various components.
**5:54** · A 9 has a loop up top and a line on the right.
**5:57** · An 8 also has a loop up top, but it's paired with another loop down low.
**6:01** · A 4 basically breaks down into three specific lines, and things like that.
**6:07** · Now in a perfect world, we might hope that each neuron in the second to last layer corresponds with one of these subcomponents, that anytime you feed in an image with, say, a loop up top, like a 9 or an 8, there's some specific neuron whose activation is going to be close to 1.
**6:24** · And I don't mean this specific loop of pixels, the hope would be that any generally loopy pattern towards the top sets off this neuron.
**6:32** · That way, going from the third layer to the last one just requires learning which combination of subcomponents corresponds to which digits.
**6:41** · Of course, that just kicks the problem down the road, because how would you recognize these subcomponents, or even learn what the right subcomponents should be?
**6:48** · And I still haven't even talked about how one layer influences the next, but run with me on this one for a moment.
**6:53** · Recognizing a loop can also break down into subproblems.
**6:57** · One reasonable way to do this would be to first recognize the various little edges that make it up.
**7:03** · Similarly, a long line, like the kind you might see in the digits 1 or 4 or 7, is really just a long edge, or maybe you think of it as a certain pattern of several smaller edges.
**7:15** · So maybe our hope is that each neuron in the second layer of the network corresponds with the various relevant little edges.
**7:23** · Maybe when an image like this one comes in, it lights up all of the neurons associated with around 8 to 10 specific little edges, which in turn lights up the neurons associated with the upper loop and a long vertical line, and those light up the neuron associated with a 9.
**7:40** · Whether or not this is what our final network actually does is another question, one that I'll come back to once we see how to train the network, but this is a hope that we might have, a sort of goal with the layered structure like this.
**7:53** · Moreover, you can imagine how being able to detect edges and patterns like this would be really useful for other image recognition tasks.
**8:00** · And even beyond image recognition, there are all sorts of intelligent things you might want to do that break down into layers of abstraction.
**8:08** · Parsing speech, for example, involves taking raw audio and picking out distinct sounds, which combine to make certain syllables, which combine to form words, which combine to make up phrases and more abstract thoughts, etc.
**8:21** · But getting back to how any of this actually works, picture yourself right now designing how exactly the activations in one layer might determine the activations in the next.
**8:30** · The goal is to have some mechanism that could conceivably combine pixels into edges, or edges into patterns, or patterns into digits.
### Edge detection example
**8:39** · And to zoom in on one very specific example, let's say the hope is for one particular neuron in the second layer to pick up on whether or not the image has an edge in this region here.
**8:51** · The question at hand is what parameters should the network have?
**8:55** · What dials and knobs should you be able to tweak so that it's expressive enough to potentially capture this pattern, or any other pixel pattern, or the pattern that several edges can make a loop, and other such things?
**9:08** · Well, what we'll do is assign a weight to each one of the connections between our neuron and the neurons from the first layer.
**9:16** · These weights are just numbers.
**9:18** · Then take all of those activations from the first layer and compute their weighted sum according to these weights.
**9:27** · I find it helpful to think of these weights as being organized into a little grid of their own, and I'm going to use green pixels to indicate positive weights, and red pixels to indicate negative weights, where the brightness of that pixel is some loose depiction of the weight's value.
**9:42** · Now if we made the weights associated with almost all of the pixels zero except for some positive weights in this region that we care about, then taking the weighted sum of all the pixel values really just amounts to adding up the values of the pixel just in the region that we care about.
**9:59** · And if you really wanted to pick up on whether there's an edge here, what you might do is have some negative weights associated with the surrounding pixels.
**10:07** · Then the sum is largest when those middle pixels are bright but the surrounding pixels are darker.
**10:14** · When you compute a weighted sum like this, you might come out with any number, but for this network what we want is for activations to be some value between 0 and 1.
**10:24** · So a common thing to do is to pump this weighted sum into some function that squishes the real number line into the range between 0 and 1.
**10:32** · And a common function that does this is called the sigmoid function, also known as a logistic curve.
**10:38** · Basically very negative inputs end up close to 0, positive inputs end up close to 1, and it just steadily increases around the input 0.
**10:49** · So the activation of the neuron here is basically a measure of how positive the relevant weighted sum is.
**10:57** · But maybe it's not that you want the neuron to light up when the weighted sum is bigger than 0.
**11:02** · Maybe you only want it to be active when the sum is bigger than say 10.
**11:06** · That is, you want some bias for it to be inactive.
**11:11** · What we'll do then is just add in some other number like negative 10 to this weighted sum before plugging it through the sigmoid squishification function.
**11:20** · That additional number is called the bias.
**11:23** · So the weights tell you what pixel pattern this neuron in the second layer is picking up on, and the bias tells you how high the weighted sum needs to be before the neuron starts getting meaningfully active.
### Counting weights and biases
**11:36** · And that is just one neuron.
**11:38** · Every other neuron in this layer is going to be connected to all 784 pixel neurons from the first layer, and each one of those 784 connections has its own weight associated with it.
**11:51** · Also, each one has some bias, some other number that you add on to the weighted sum before squishing it with the sigmoid.
**11:58** · And that's a lot to think about!
**11:59** · With this hidden layer of 16 neurons, that's a total of 784 times 16 weights, along with 16 biases.
**12:08** · And all of that is just the connections from the first layer to the second.
**12:12** · The connections between the other layers also have a bunch of weights and biases associated with them.
**12:18** · All said and done, this network has almost exactly 13,000 total weights and biases.
**12:23** · 13,000 knobs and dials that can be tweaked and turned to make this network behave in different ways.
### How learning relates
**12:31** · So when we talk about learning, what that's referring to is getting the computer to find a valid setting for all of these many many numbers so that it'll actually solve the problem at hand.
**12:42** · One thought experiment that is at once fun and kind of horrifying is to imagine sitting down and setting all of these weights and biases by hand, purposefully tweaking the numbers so that the second layer picks up on edges, the third layer picks up on patterns, etc.
**12:56** · I personally find this satisfying rather than just treating the network as a total black box, because when the network doesn't perform the way you anticipate, if you've built up a little bit of a relationship with what those weights and biases actually mean, you have a starting place for experimenting with how to change the structure to improve.
**13:14** · Or when the network does work but not for the reasons you might expect, digging into what the weights and biases are doing is a good way to challenge your assumptions and really expose the full space of possible solutions.
### Notation and linear algebra
**13:26** · By the way, the actual function here is a little cumbersome to write down, don't you think?
**13:32** · So let me show you a more notationally compact way that these connections are represented.
**13:37** · This is how you'd see it if you choose to read up more about neural networks.
**13:40** · Organize all of the activations from one layer into a column as a vector.
**13:48** · Then organize all of the weights as a matrix, where each row of that matrix corresponds to the connections between one layer and a particular neuron in the next layer.
**13:58** · What that means is that taking the weighted sum of the activations in the first layer according to these weights corresponds to one of the terms in the matrix vector product of everything we have on the left here.
**14:14** · By the way, so much of machine learning just comes down to having a good grasp of linear algebra, so for any of you who want a nice visual understanding for matrices and what matrix vector multiplication means, take a look at the series I did on linear algebra, especially chapter 3.
**14:29** · Back to our expression, instead of talking about adding the bias to each one of these values independently, we represent it by organizing all those biases into a vector, and adding the entire vector to the previous matrix vector product.
**14:43** · Then as a final step, I'll wrap a sigmoid around the outside here, and what that's supposed to represent is that you're going to apply the sigmoid function to each specific component of the resulting vector inside.
**14:55** · So once you write down this weight matrix and these vectors as their own symbols, you can communicate the full transition of activations from one layer to the next in an extremely tight and neat little expression, and this makes the relevant code both a lot simpler and a lot faster, since many libraries optimize the heck out of matrix multiplication.
### Recap
**15:17** · Remember how earlier I said these neurons are simply things that hold numbers?
**15:22** · Well of course the specific numbers that they hold depends on the image you feed in, so it's actually more accurate to think of each neuron as a function, one that takes in the outputs of all the neurons in the previous layer and spits out a number between 0 and 1.
**15:39** · Really the entire network is just a function, one that takes in 784 numbers as an input and spits out 10 numbers as an output.
**15:47** · It's an absurdly complicated function, one that involves 13,000 parameters in the forms of these weights and biases that pick up on certain patterns, and which involves iterating many matrix vector products and the sigmoid squishification function, but it's just a function nonetheless.
**16:03** · And in a way it's kind of reassuring that it looks complicated.
**16:07** · I mean if it were any simpler, what hope would we have that it could take on the challenge of recognizing digits?
**16:13** · And how does it take on that challenge?
**16:15** · How does this network learn the appropriate weights and biases just by looking at data?
**16:20** · Well that's what I'll show in the next video, and I'll also dig a little more into what this particular network we're seeing is really doing.
### Some final words
**16:27** · Now is the point I suppose I should say subscribe to stay notified about when that video or any new videos come out, but realistically most of you don't actually receive notifications from YouTube, do you?
**16:38** · Maybe more honestly I should say subscribe so that the neural networks that underlie YouTube's recommendation algorithm are primed to believe that you want to see content from this channel get recommended to you.
**16:48** · Anyway, stay posted for more.
**16:50** · Thank you very much to everyone supporting these videos on Patreon.
**16:54** · I've been a little slow to progress in the probability series this summer, but I'm jumping back into it after this project, so patrons you can look out for updates there.
### ReLU vs Sigmoid
**17:03** · To close things off here I have with me Lisha Li who did her PhD work on the theoretical side of deep learning and who currently works at a venture capital firm called Amplify Partners who kindly provided some of the funding for this video.
**17:15** · So Lisha one thing I think we should quickly bring up is this sigmoid function.
**17:19** · As I understand it early networks use this to squish the relevant weighted sum into that interval between zero and one, you know kind of motivated by this biological analogy of neurons either being inactive or active.
**17:30** · Exactly. But relatively few modern networks actually use sigmoid anymore.
**17:34** · Yeah. It's kind of old school right?
**17:35** · Yeah or rather ReLU seems to be much easier to train.
**17:39** · And ReLU, ReLU stands for rectified linear unit?
**17:42** · Yes it's this kind of function where you're just taking a max of zero and a where a is given by what you were explaining in the video and what this was sort of motivated from I think was a partially by a biological analogy with how neurons would either be activated or not.
**18:01** · And so if it passes a certain threshold it would be the identity function but if it did not then it would just not be activated so it'd be zero so it's kind of a simplification.
**18:11** · Using sigmoids didn't help training or it was very difficult to train at some point and people just tried ReLU and it happened to work very well for these incredibly deep neural networks.
**18:25** · All right thank you Lisha.

Timestamped transcript — 20 KB · contentType: "video"

Playlistyoutube.com/playlist?list=PLrAXtm…

What YouTube serves

MIT Select Lectures playlist page on YouTube as served to anonymous visitors

1.1 MB of rendered HTML — banner, video rails, sign-in prompts

What the API returns

markdown
# Select Lectures
Some lectures on deep learning, deep reinforcement learning, autonomous vehicles, and artificial intelligence. https://deeplearning.mit.edu
## Videos (2)
1. [Deep Learning State of the Art (2020)](https://www.youtube.com/watch?v=0VH1Lim8gL8&list=PLrAXtmErZgOeiKm4sgNOknGvNjby9efdf)
Lex Fridman · 1:27:41
2. [Deep Learning Basics: Introduction and Overview](https://www.youtube.com/watch?v=O5xeyoRL95U&list=PLrAXtmErZgOeiKm4sgNOknGvNjby9efdf)
Lex Fridman · 1:08:06

Structured listing — 490 B · videoCount: 2 · contentType: "playlist"

Music videoyoutube.com/watch?v=dQw4w9WgXcQ

What YouTube serves

Rick Astley music video on YouTube as served to anonymous visitors

2.1 MB of rendered HTML — same player chrome, lyrics hidden in the caption track

What the API returns

markdown
## Transcript
**0:01** · \[♪♪♪\]
**0:18** · ♪ We're no strangers to love ♪ ♪ You know the rules and so do I ♪ ♪ A full commitment's what I'm thinking of ♪ ♪ You wouldn't get this from any other guy ♪ ♪ I just wanna tell you how I'm feeling ♪
**0:40** · ♪ Gotta make you understand ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪ ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪
**1:00** · ♪ We've known each other for so long ♪ ♪ Your heart's been aching but you're too shy to say it ♪ ♪ Inside we both know what's been going ♪ ♪ We know the game and we're gonna play it ♪ ♪ And if you ask me how I'm feeling ♪
**1:22** · ♪ Don't tell me you're too blind to see ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪ ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪
**1:50** · ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪ ♪ (Ooh, give you up) ♪ ♪ (Ooh, give you up) ♪
**2:08** · ♪ Never gonna give, never gonna give ♪ ♪ (Give you up) ♪ ♪ Never gonna give, never gonna give ♪ ♪ (Give you up) ♪ ♪ We've known each other for so long ♪ ♪ Your heart's been aching but you're too shy to say it ♪ ♪ Inside we both know what's been going ♪ ♪ We know the game and we're gonna play it ♪ ♪ I just wanna tell you how I'm feeling ♪
**2:38** · ♪ Gotta make you understand ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪ ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪
**3:06** · ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪ ♪ Never gonna give you up ♪ ♪ Never gonna let you down ♪ ♪ Never gonna run around and desert you ♪ ♪ Never gonna make you cry ♪ ♪ Never gonna say goodbye ♪ ♪ Never gonna tell a lie and hurt you ♪

Lyric transcript — 2.2 KB · contentType: "video" · availability: "full"

What is covered, by URL pattern

YouTube support is measured per URL pattern, not claimed per domain. Every row below is verified against the live crawler.

URL patternStatusWhat you get
/watch?v=<id>
Supported
Timestamped transcript plus title — read straight from the caption track the page already carries.
youtu.be/<id>
Supported
Short URLs normalize to the same watch page — identical output.
/playlist?list=<id>
Supported
Playlist title, description, and one structured entry per video — title, uploader, duration.
videos without captions
Partial
No caption track means no transcript — you get the title and description with availability: "partial" and the missing fields named in unavailableFields.

YouTube transcripts without the Data API

Point the Crawl endpoint at a YouTube URL and the request is routed to a dedicated parser. Videos return the caption track as timestamped Markdown; playlists return structured listings. The official Data API gates captions behind OAuth and only serves them for your own uploads — this path reads the track YouTube already publishes on the public page.

Captions, not pixels

The parser reads the caption track embedded in the watch page — no headless browser, no audio transcription step, no frame scraping.

Playlists stay structured

A playlist URL returns one entry per video with title, channel, and duration — usable as a queue manifest, not a scraped list.

Honest availability flags

results.metadata.availability marks full or partial coverage, and unavailableFields names exactly what YouTube did not publish — no silent gaps.

Verified per URL pattern

Every row in the matrix is reproduced from a live crawl of a real URL — support is measured per pattern, not claimed per domain.

What is a YouTube scraper API?

A YouTube scraper API is an HTTP interface that takes a YouTube URL and returns the page’s usable content in a structured, model-ready format. The interesting part for most pipelines is the transcript: the official YouTube Data API only exposes captions through an OAuth flow, and only for videos the authenticated account owns. Search1API’s Crawl endpoint takes the route the page itself offers — the caption track embedded for viewers — and returns it as timestamped Markdown for any public video. Playlists come back as structured listings rather than page soup.

Implementation path

Typical workflow

Send a public YouTube URL to the Crawl endpoint and get back structured Markdown — timestamped transcripts for videos, structured entries for playlists. No Google account needed.

1

POST a YouTube URL to the Crawl endpoint — no Google account needed.

2

The URL is matched against the pattern rules and routed to the dedicated YouTube parser.

3

Videos return a timestamped transcript; playlists return a structured listing — both carry results.metadata.platform and contentType.

4

Captionless videos and live streams come back as honest partials with availability and unavailableFields set — never fabricated text.

Where teams use it

Feed lectures, conference talks, and interviews into RAG pipelines as timestamped text.

Build subtitle and translation corpora from public caption tracks.

Turn playlists into structured course or episode manifests with one call per playlist.

Summarize long videos — the transcript arrives chunked by timestamp, ready for a context window.

FAQ

Do I need a Google account or the YouTube Data API?

No. The parser reads the caption track YouTube serves on the public watch page — the same track any viewer can enable. No OAuth flow, no API console setup, and no channel ownership requirement, unlike the official captions endpoint.

Which YouTube URLs are supported?

Watch URLs (youtube.com/watch?v=…), short URLs (youtu.be/…), and playlists (youtube.com/playlist?list=…). Shorts, channel pages, and search results are not claimed — the matrix shows exactly what was verified.

What about videos without captions?

You get an honest partial: title and description with metadata.availability set to "partial" and the missing fields listed in unavailableFields. Live streams behave the same way until captions exist.

Does it work with music videos and auto-generated captions?

Yes — auto-generated caption tracks are read the same way as uploaded ones. Music videos typically return the lyric track, as the demo shows.

What format does the content come back in?

Markdown. Videos return a ## Transcript section with **timestamp** · text segments; playlists return a numbered listing. results.metadata carries platform, contentType, videoId or playlistId, and availability flags.

Is scraping YouTube legal?

We only read the caption tracks and page data YouTube serves to anonymous visitors — no login, no session sharing, no circumvention of access controls. Whether a specific use complies with applicable law and YouTube’s terms depends on your jurisdiction and use case, so confirm that with your own counsel.